<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://mitchmurphy.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://mitchmurphy.io/" rel="alternate" type="text/html" /><updated>2024-11-27T11:17:08-05:00</updated><id>https://mitchmurphy.io/feed.xml</id><title type="html">Mitch Murphy</title><subtitle>DevOps Engineer</subtitle><author><name>Mitch Murphy</name></author><entry><title type="html">Cluster Mesh with Cilium Overview</title><link href="https://mitchmurphy.io/cilium-cluster-mesh-overview/" rel="alternate" type="text/html" title="Cluster Mesh with Cilium Overview" /><published>2024-09-19T00:00:00-04:00</published><updated>2024-09-19T00:00:00-04:00</updated><id>https://mitchmurphy.io/cilium-cluster-mesh-overview</id><content type="html" xml:base="https://mitchmurphy.io/cilium-cluster-mesh-overview/"><![CDATA[<h1 id="cluster-mesh-with-cilium-overview">Cluster Mesh with Cilium Overview</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Cluster Mesh with Cilium Overview</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2024-09-18</span>
</code></pre></div></div>

<hr />

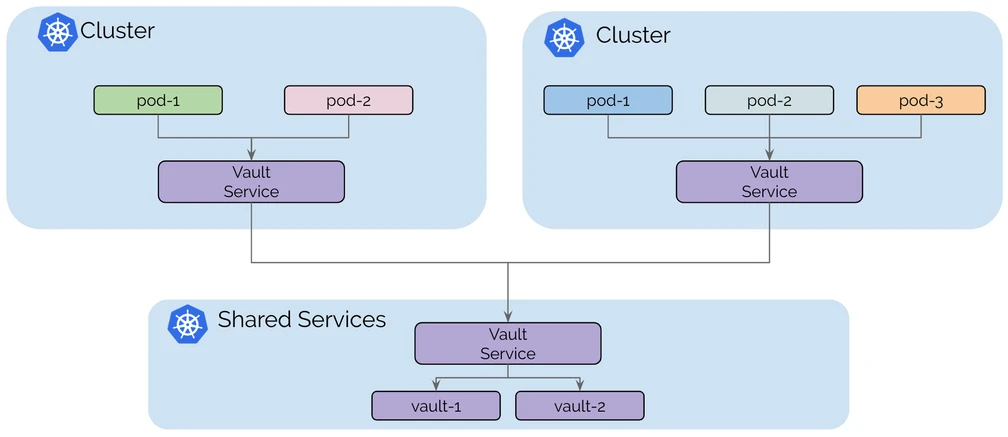
<p>This will be a series of blog posts, first discussing some high-level background on a few of the technologies used. A future post will detail the technical implementation details for reproducing most of what was covered in a Lunch-N-Learn held on November 19, 2024. This demo session discussed configuring, deploying, testing and demoing Cilium Cluster Mesh. Specifically, we demonstrated the use of global services (and shared ingress) to significantly improve resiliency/availability, as well as splitting out stateless and stateful workloads (in this case observability metrics/logs using LGTM). We will also briefly discuss deploying a lightweight service mesh using Cilium 1.16.1, securing workloads via SPIRE/SPIFFE as well as node encryption via Wireguard.</p>

<h2 id="pre-requisites">Pre-requisites</h2>

<p>Before configuring Cilium Cluster Mesh, ensure the following prerequisites are met:</p>

<ul>
  <li><strong>Unique CIDR Ranges for Pods and Services</strong>: Each Kubernetes cluster must have unique POD and SERVICES CIDR ranges to avoid conflicts and enable seamless cross-cluster communication via IP addresses.</li>
  <li><strong>Unique Node CIDRs and IP Connectivity</strong>: Nodes in all clusters must have unique CIDR ranges, and IP connectivity between nodes in different clusters is essential. In my lab environment, I use direct connections between clusters, but per Cilium documentation, it is also possible to achieve connectivity using a VPN or other networking solutions like BGP (Border Gateway Protocol) or VXLAN encapsulation for workloads spread across clouds and regions.</li>
  <li><strong>Clustermesh API Service Exposure</strong>: Cilium pods need to connect to the Clustermesh API service exposed on each interconnected cluster. While <strong>NodePort</strong> can be used to expose this service, this is not recommended for production environments. Instead, using Kubernetes ingress or <strong>LoadBalancer</strong> services is preferred for production setups to ensure robustness and security. I will be using a <strong>LoadBalancer</strong> service in this demo, and because I am using on-prem hardware this is possible via <strong>MetalLB</strong>. In a future article I plan to replace certain MetalLB functionality with Cilium.</li>
  <li><strong>Consistent Certificate Authority (CA)</strong>: To configure Cilium Cluster Mesh using the Helm chart without additional manual steps, the Cilium CNI in all clusters must be configured with the same Certificate Authority (CA). This ensures mutual trust between clusters, eliminating the need to manually generate or distribute certificates. This configuration can be specified in the Helm chart values file, allowing for seamless Cluster Mesh setup across clusters. Here, Ansible plays are resposible for creating this CA and “templating” the values file with this information.</li>
</ul>

<h3 id="configuration">Configuration</h3>

<ul>
  <li>RKE2: v1.31.0</li>
  <li>Cilium: v1.16.1</li>
  <li>Rocky Linux 9.4</li>
  <li>Kernel 6.10.11-1</li>
  <li>4 vCPU’s and 8GB RAM per node</li>
  <li>Currently deployed on Windows Data Center 2022, using:
    <ul>
      <li>Ansible</li>
      <li>Packer</li>
    </ul>
  </li>
  <li>Kuberenetes resources:
    <ul>
      <li>Helm</li>
      <li>Kustomize</li>
      <li>ArgoCD</li>
      <li>MetalLB</li>
      <li>NGINX Ingress Controller</li>
      <li>Prometheus CRDs</li>
      <li>kube-state-metrics</li>
      <li>LGTM-distributed stack</li>
      <li>Grafana Alloy</li>
      <li>nfs-subdir-external-provisioner</li>
    </ul>
  </li>
</ul>

<h2 id="cilium-introduction">Cilium Introduction</h2>

<p>Cilium is an advanced Container Network Interface (CNI) solution that leverages eBPF (Extended Berkeley Packet Filter), a powerful Linux kernel technology, to provide highly scalable and efficient networking, security, and observability for containerized workloads in Kubernetes.</p>

<p>In Kubernetes, networking is critical because it allows communication between different components like pods, services, and nodes. Traditionally, Kubernetes networking has relied on various CNIs like Flannel, Calico, or Weave to handle the connectivity between pods and services. However, Cilium stands out because it uses eBPF, which allows it to dynamically program the Linux kernel to handle packet filtering, forwarding, and security enforcement at the kernel level, offering several benefits:</p>

<ol>
  <li><strong>Fine-Grained Network Security</strong>: Cilium provides a powerful Network Policy implementation that is capable of enforcing security policies based on the rich context of application-layer metadata. This goes beyond basic IP-based policies, allowing for policies that are aware of protocols, services, and even individual application processes.</li>
  <li><strong>Scalable Performance</strong>: Leveraging eBPF, Cilium can deliver networking with significantly lower overhead compared to traditional iptables-based approaches. eBPF runs inside the Linux kernel without needing to go back to user space, ensuring high performance and reduced latency.</li>
  <li><strong>Layer 7 Policies and Security</strong>: Cilium supports layer 7 (L7) visibility and filtering, which allows for enforcing security policies based on application-level protocols such as HTTP, gRPC, or Kafka. This is particularly useful in microservices architectures where services are constantly communicating over well-defined APIs.</li>
  <li><strong>Built-In Observability</strong>: Cilium offers Hubble, a built-in observability tool that provides deep insights into the networking behavior of Kubernetes clusters. With Hubble, administrators can visualize traffic flows, monitor security policies, and debug networking issues across their clusters in real time.</li>
  <li><strong>Service Mesh Integration</strong>: Cilium can integrate with service meshes like Istio or Envoy to provide networking and security enforcement without the need for sidecar proxies. By using eBPF, Cilium can perform many of the functions traditionally handled by service meshes more efficiently, reducing the overhead typically associated with sidecar containers.</li>
  <li><strong>Native Kubernetes Integration</strong>: Cilium is fully compatible with Kubernetes and supports essential features such as pod-to-pod communication, service discovery, and load balancing. It can also integrate with Kubernetes-native constructs like Ingress controllers and CoreDNS, making it a versatile and Kubernetes-first networking solution.</li>
  <li><strong>Multi-Cluster Networking (Cluster Mesh)</strong>: In addition to single-cluster setups, Cilium allows for seamless inter-cluster networking through its Cluster Mesh feature. This means that multiple Kubernetes clusters can be interconnected, and services or pods from different clusters can communicate as if they were part of the same network. Cilium automates much of the complexity associated with this multi-cluster networking, such as managing IP routing, load balancing, and network policies.</li>
</ol>

<p>Cilium provides a robust, scalable, and secure solution for networking in Kubernetes environments. By leveraging eBPF, it offers more advanced networking capabilities compared to traditional CNIs, while also improving observability and security. For organizations running cloud-native applications at scale, Cilium’s rich feature set makes it an attractive choice for Kubernetes networking.</p>

<h3 id="ebpf">eBPF</h3>

<p>eBPF (Extended Berkeley Packet Filter) is a powerful feature within the Linux kernel that allows for efficient, programmable control over various kernel activities. It originated from the classical BPF (cBPF), which was developed in 1992 to filter network packets by avoiding unnecessary copying of data from the kernel to userspace. eBPF expands on this concept, providing enhanced functionality and flexibility.</p>

<p>While cBPF only allowed forward jumps and was mainly focused on network packet filtering, eBPF introduced several significant improvements:</p>

<ul>
  <li><strong>Increased Resources</strong>: eBPF provides 10 registers and supports load/store instructions for 1–8 bytes, greatly enhancing its capabilities.</li>
  <li><strong>Control Flow Enhancements</strong>: Unlike cBPF, eBPF supports both forward and backward jumps, allowing for loops, though the kernel ensures these loops terminate to maintain system safety.</li>
  <li><strong>Data Structures</strong>: eBPF introduced more complex data structures such as hash tables and arrays, allowing programs to handle more sophisticated operations beyond simple packet filtering.</li>
</ul>

<p>eBPF can be used at various hook points within the kernel, such as at incoming and outgoing network packets, enabling real-time inspection, filtering, and manipulation. This flexibility allows eBPF to perform tasks like packet mangling, forwarding, and encapsulation.</p>

<p>The safety of eBPF programs is guaranteed by an in-kernel verifier, ensuring that the programs are safe to run and won’t crash the system. Additionally, a Just-In-Time (JIT) compiler translates eBPF bytecode into CPU-specific machine code, optimizing performance for native execution.</p>

<p>Modern systems, such as <strong>Cilium</strong>, leverage eBPF to enhance networking, security, and observability. Cilium can detect kernel features dynamically, using the latest kernel capabilities when available, demonstrating the continuous evolution and expanding use cases of eBPF beyond its original networking focus.</p>

<p>eBPF is widely used at large tech companies, such as Netflix and Palantir, to not only optimize performance by reducing latecy, but also for deep visibility into processes that would otherwise be near impossible. You can read such a technique on the Netflix <a href="https://netflixtechblog.com/noisy-neighbor-detection-with-ebpf-64b1f4b3bbdd">blog</a> that details how they use eBPF to solve the “noise neighbors” problem. Read more at <a href="https://ebpf.io/">ebpf.io</a></p>

<h2 id="pod-routing">Pod Routing</h2>

<p>Cilium offers a powerful enhancement to Kubernetes networking by replacing the default kube-proxy component with an eBPF-based solution. The kube-proxy replacement significantly optimizes pod-to-pod communication, service load balancing, and network policy enforcement in Kubernetes environments. Here’s an in-depth look at how pod routing works in Cilium with kube-proxy replacement, using publicly available information and insights from the official Cilium documentation on Cluster Mesh.</p>

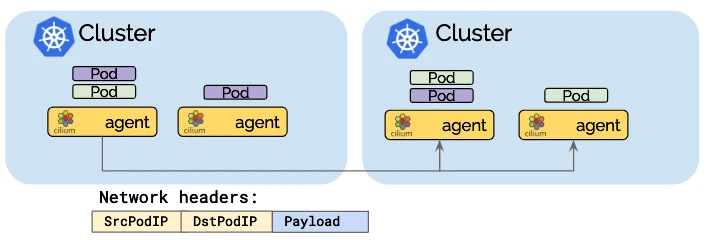
<h4 id="direct-routing-mode">Direct-routing mode</h4>

<p><img src="../images/posts/ciliumclustermeshpod.png" width="100%" height="auto" alt="Image alt text" /></p>

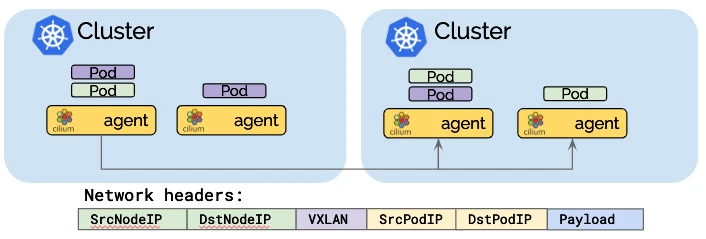
<h4 id="tunneling-mode">Tunneling mode</h4>

<p><img src="../images/posts/tunneling_mode.png" width="100%" height="auto" alt="Image alt text" /></p>

<h3 id="what-is-kube-proxy-and-why-replace-it">What Is Kube-Proxy and Why Replace It?</h3>

<p>In a standard Kubernetes setup, kube-proxy is responsible for implementing service networking by managing IP tables or IPVS rules that define how traffic flows between pods, services, and external clients. While kube-proxy is functional, it has limitations, particularly around scalability and performance. Kube-proxy uses a user-space model to route traffic, which introduces overhead in terms of latency and CPU utilization.</p>

<p>Cilium’s kube-proxy replacement addresses these issues by using eBPF to handle networking functions directly in the Linux kernel, removing the need for iptables-based routing. This results in faster, more efficient pod-to-pod communication, and improved load balancing.</p>

<p>When using Cilium with kube-proxy replacement, the primary difference in pod routing is that service load balancing and traffic routing are handled entirely in the kernel using eBPF, without relying on kube-proxy’s traditional user-space or iptables mechanism. Here’s how it works:</p>

<h3 id="pod-to-pod-communication">Pod-to-Pod Communication</h3>

<p>In Kubernetes, when a pod wants to communicate with another pod, it typically does so by referencing the service that fronts the destination pod. With Cilium’s kube-proxy replacement:</p>

<p>eBPF Programs in the Kernel: Cilium installs eBPF programs directly in the Linux kernel to handle all traffic flows. When a packet originates from a pod, Cilium’s eBPF program intercepts the packet at the kernel level, determining the most efficient route based on the pod’s destination.
Direct Routing via Cilium BPF Maps: Cilium maintains an internal eBPF map that keeps track of all pod IPs and their locations. This allows Cilium to bypass the kube-proxy and the entire iptables layer, performing direct routing to the destination pod. It can route the packet to the correct pod without going through a complex chain of network rules.
Low-Latency Routing: The direct routing enabled by eBPF eliminates unnecessary hops or processing delays introduced by user-space proxies, significantly reducing latency and overhead.</p>

<h3 id="cross-node-traffic-routing">Cross-Node Traffic Routing</h3>

<p>In multi-node Kubernetes clusters, traffic often needs to be routed between pods located on different nodes. Cilium, using eBPF and kube-proxy replacement, handles cross-node traffic in a much more efficient way:</p>

<p>NodePort Without Kube-Proxy: Cilium supports NodePort functionality even without kube-proxy. When traffic hits a NodePort, Cilium can directly route the packet to the correct backend pod across nodes using the eBPF map. This ensures that NodePort services continue to function as expected, with reduced latency.
Cilium BPF Node Encapsulation: For cross-node traffic, Cilium leverages an eBPF-based node encapsulation mechanism (using VXLAN or Geneve) to route traffic efficiently between nodes. This allows pods on different nodes to communicate as if they were on the same node, maintaining network transparency across the cluster.</p>

<h3 id="benefits-of-ciliums-kube-proxy-replacement">Benefits of Cilium’s Kube-Proxy Replacement</h3>

<p>Improved Performance: By bypassing kube-proxy and handling traffic directly in the kernel, Cilium reduces the overhead associated with user-space proxies and iptables rules. This results in lower latency, reduced CPU usage, and faster pod-to-pod communication.</p>

<p>Scalability: Traditional kube-proxy setups can struggle with scalability, especially in large clusters with thousands of services. Cilium’s eBPF-based approach scales much better because it does not require the management of large sets of iptables rules. Instead, eBPF maps are highly efficient and can handle large-scale clusters with ease.</p>

<p>Enhanced Observability and Security: Cilium’s eBPF programs provide rich observability into network traffic, enabling better monitoring and debugging. This also allows for advanced security features, such as network policies that operate at both the layer 3/4 and layer 7 levels, something not possible with kube-proxy.</p>

<p>Seamless Multi-Cluster Networking: With Cilium Cluster Mesh, services and pods across multiple clusters are seamlessly integrated. Cilium handles routing between clusters, using eBPF to efficiently direct traffic between nodes and services regardless of cluster boundaries.</p>

<h2 id="cluster-mesh">Cluster Mesh</h2>

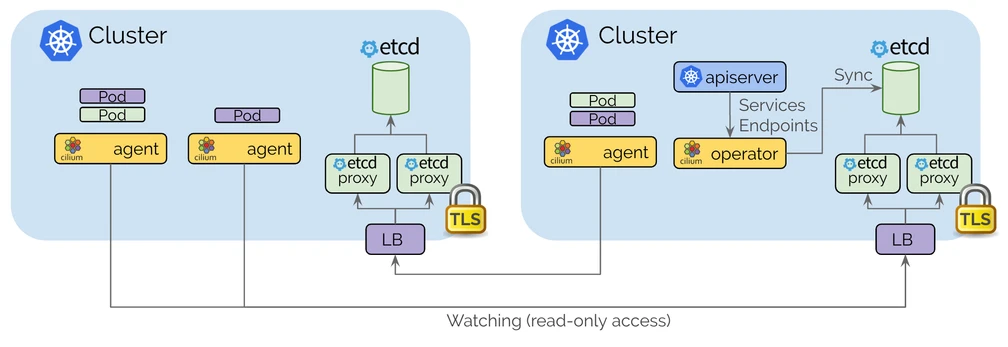
<p>Cilium Cluster Mesh is a powerful solution for multi-cluster environments, providing seamless networking across Kubernetes clusters. With the introduction of Helm-based configuration in Cilium 1.14.0, it has become significantly easier to automate Cluster Mesh setups, making it a viable solution even for environments that require frequent changes or updates. Integrating Cilium Cluster Mesh with a GitOps workflow allows for continuous, declarative management of your cluster networking, making it adaptable to both test and production environments.</p>

<p>Until recently, configuring Cilium Cluster Mesh required several manual steps, such as creating and copying certificates between clusters to establish secure connections. However, starting from Cilium version 1.14.0, administrators can configure Cluster Mesh using a GitOps approach by leveraging the Cilium Helm chart. This eliminates the need for manual certificate distribution or bash scripting. By installing the Cilium Helm chart with the correct values, Cluster Mesh becomes operational immediately.</p>

<p>This article outlines the steps to deploy and configure interconnected Kubernetes clusters with Cilium Cluster Mesh, using the Cilium Helm Chart (version <strong>1.16.1</strong>).</p>

<p><img src="../images/posts/ciliumclustermeshcp.png" width="100%" height="auto" alt="Image alt text" /></p>

<h3 id="global-services">Global Services</h3>

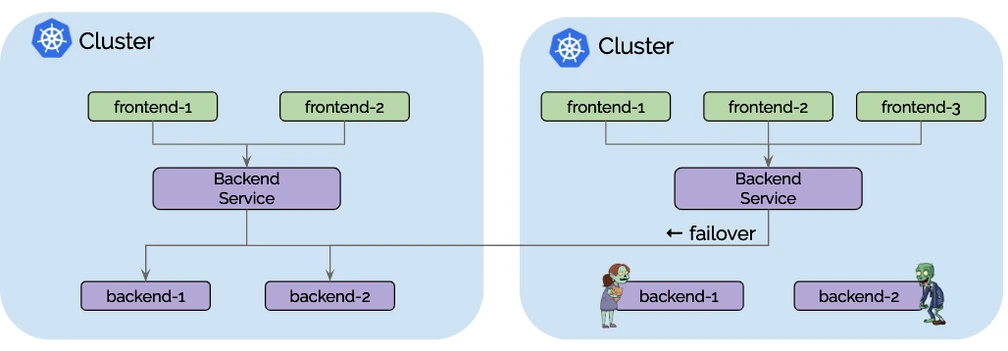
<p>The Global Services feature of Cilium Cluster Mesh allows services deployed across multiple Kubernetes clusters to be exposed under a single DNS name or IP address, enabling pods in one cluster to seamlessly access services in another cluster. This creates a unified service discovery mechanism across clusters, providing seamless connectivity and availability of services, no matter where they are physically located.</p>

<p>In a multi-cluster setup, this feature provides significant advantages, particularly for improving resiliency and high availability (HA) in the following scenarios:</p>

<p><img src="../images/posts/ciliumclustermeshglobalsvs.png" width="100%" height="auto" alt="Image alt text" /></p>

<h4 id="single-availability-zone-single-az">Single Availability Zone (Single AZ)</h4>

<p>In a single AZ, Cilium’s Global Services feature enhances resilience by enabling load balancing and failover capabilities between clusters. Even though both clusters reside within the same AZ, the Global Services feature ensures that the workload is distributed across the clusters to prevent single points of failure. If one cluster experiences an issue (such as a node failure or a pod crash), traffic can automatically be redirected to another cluster where the service is available. This ensures service continuity, even within a single AZ environment.</p>

<p>How It Works:</p>

<ul>
  <li>Global services rely on Cilium’s service load-balancing capabilities, which utilize eBPF to distribute traffic at the kernel level.</li>
  <li>A service deployed in one cluster (Cluster A) can be made available in another cluster (Cluster B), and vice versa.</li>
  <li>DNS-based Service Discovery: Cilium integrates with Kubernetes’ service discovery (via CoreDNS) to provide a unified DNS name that routes requests to all instances of a service across clusters. Pods querying the service by DNS get directed to any of the available service instances, regardless of the cluster.</li>
  <li>If a pod in Cluster A tries to access a service that is unavailable within its own cluster, Cilium automatically reroutes the request to the healthy service endpoint in Cluster B.</li>
</ul>

<p>Benefits:</p>

<ul>
  <li>Resiliency: If a cluster experiences service degradation, traffic is routed to another healthy cluster without downtime.</li>
  <li>Load Balancing: Requests can be balanced across all clusters, ensuring optimal resource utilization and performance.</li>
</ul>

<h4 id="multi-az-multiple-availability-zones">Multi-AZ (Multiple Availability Zones)</h4>

<p>In a multi-AZ setup, clusters are spread across different availability zones within the same region. The Global Services feature of Cilium Cluster Mesh provides cross-AZ failover capabilities, enhancing resiliency against the failure of an entire AZ, which is a more significant failure scenario compared to intra-cluster or single-node failures.</p>

<p>How It Works:</p>

<ul>
  <li>Similar to the single AZ scenario, Global Services allow traffic to be load-balanced between clusters in different AZs.</li>
  <li>In case one AZ becomes completely unavailable due to a failure or maintenance activity, traffic is automatically directed to services in clusters located in the healthy AZs.</li>
  <li>eBPF-driven Load Balancing ensures minimal latency by selecting the most optimal service endpoint, regardless of whether it’s in the same AZ or a different AZ.</li>
  <li>DNS-based service discovery continues to work across AZs, and clients are oblivious to the underlying infrastructure details, as they simply use the same DNS name to access services.</li>
</ul>

<p>Benefits:</p>

<ul>
  <li>High Availability: If an entire AZ goes down, the Global Services feature ensures that services remain available in other AZs.</li>
  <li>Fault Tolerance: Traffic is intelligently routed between AZs, avoiding the risk of downtime even in major failure scenarios.</li>
  <li>Load Balancing Across AZs: Distributing traffic across multiple AZs ensures better resource utilization and performance across the entire infrastructure.</li>
</ul>

<h4 id="multi-region">Multi-Region</h4>

<p>In a multi-region setup, clusters are distributed across entirely different geographical regions. This architecture can provide the highest level of availability, as regions are isolated from each other in terms of geography, power, networking, and other factors. Cilium Cluster Mesh, with its Global Services feature, supports cross-region service discovery and load balancing, ensuring resilience and disaster recovery in case of large-scale regional failures.</p>

<p>How It Works:</p>

<ul>
  <li>Similar to multi-AZ scenarios, the Global Services feature allows services to be exposed across clusters that are deployed in different regions.</li>
  <li>A pod in one region (Region A) can seamlessly communicate with a service in another region (Region B), thanks to the unified service discovery and routing capabilities of Cilium.</li>
  <li>Traffic is routed between regions based on DNS responses and service load balancing.</li>
  <li>Geo-Proximity Routing: Depending on the service configuration, Cilium can prefer service endpoints within the same region (to reduce latency) and only route to another region in case of service unavailability within the local region.</li>
  <li>Global services in a multi-region setup also enable disaster recovery strategies where traffic can be entirely re-routed to another region in case of catastrophic failure in one region.</li>
</ul>

<p>Benefits:</p>

<ul>
  <li>Resiliency Across Regions: Even if an entire region becomes unavailable, the Global Services feature allows traffic to be routed to another region, ensuring business continuity.</li>
  <li>Geographic Load Balancing: Cilium can balance traffic not only across clusters but also across regions, allowing for reduced latency by selecting the nearest service endpoint.</li>
  <li>Disaster Recovery: Multi-region setups ensure that a catastrophic event affecting one region doesn’t result in a complete service outage. Cilium seamlessly reroutes traffic to clusters in unaffected regions.</li>
</ul>

<h4 id="service-failover-and-traffic-management">Service Failover and Traffic Management</h4>

<p>One of the core strengths of Cilium’s Global Services feature is its intelligent traffic management and automatic failover. By using eBPF at the kernel level, Cilium can quickly detect failures and reroute traffic without introducing significant latency or downtime. Additionally, the multi-cluster architecture allows for sophisticated traffic shaping policies, such as:</p>

<ul>
  <li>Weighted Load Balancing: Distribute traffic unevenly across clusters or regions based on their capacity or health.</li>
  <li>Service Affinity: Prefer local service instances over remote ones to reduce latency while still maintaining availability if the local instance fails.</li>
</ul>

<p><img src="../images/posts/ciliumclustermeshfailover.png" width="100%" height="auto" alt="Image alt text" /></p>

<h5 id="summary-of-benefits">Summary of Benefits</h5>

<p>The Global Services feature of Cilium Cluster Mesh plays a critical role in improving resiliency and high availability across various cluster architectures, including single AZ, multi-AZ, and multi-region deployments. Here’s a summary of how it achieves this:</p>

<ul>
  <li>Resilience: Global Services ensures that service requests are not limited to a single cluster. In case of cluster or AZ failure, services remain accessible by rerouting traffic to healthy clusters.</li>
  <li>High Availability: With service failover across AZs and regions, Cilium ensures that services remain up even in the face of significant infrastructure failures.</li>
  <li>Performance Optimization: Cilium’s eBPF-powered load balancing intelligently routes traffic based on proximity and service health, ensuring optimal performance across clusters and regions.</li>
  <li>Disaster Recovery: In multi-region deployments, Cilium allows services to recover from a complete regional failure by rerouting traffic to healthy regions, maintaining business continuity.</li>
</ul>

<h3 id="service-discovery">Service Discovery</h3>

<p>In Kubernetes, service discovery is the process through which one service can discover and communicate with another, usually through DNS. Cilium integrates seamlessly with Kubernetes’ built-in service discovery mechanisms while extending its capabilities through eBPF.</p>

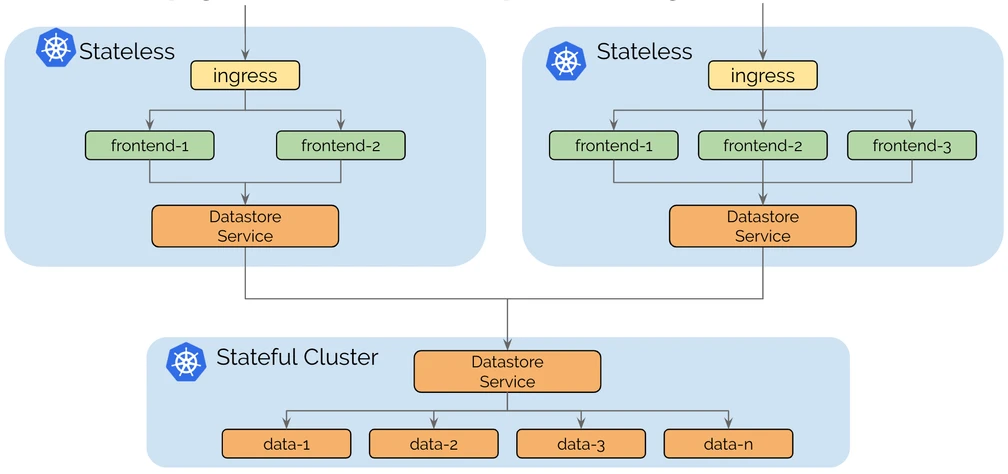
<p><img src="../images/posts/ciliumclustermeshsplit.png" width="100%" height="auto" alt="Image alt text" /></p>

<p>Key Components of Service Discovery in Cilium:</p>
<ul>
  <li>Kube-DNS Integration: Cilium integrates with Kubernetes’ native DNS system (typically CoreDNS) to allow pods to resolve services using standard DNS names (e.g., <code class="language-plaintext highlighter-rouge">service.namespace.svc.cluster.local</code>). This integration ensures that Kubernetes’ service discovery process remains consistent with Cilium’s networking layer.</li>
  <li>eBPF-based DNS Inspection: Cilium leverages eBPF to inspect DNS traffic in the kernel, enabling faster service discovery and the ability to enforce network policies based on DNS lookups. This allows for DNS-aware security policies, where network access can be restricted or permitted based on the domain name being queried.</li>
  <li>Multi-Cluster Service Discovery: In multi-cluster environments with Cilium Cluster Mesh, Cilium extends service discovery across clusters. Services from different clusters can be discovered and accessed seamlessly as if they were part of the same cluster. Cilium automatically handles the cross-cluster service discovery using DNS-based service records (e.g., for Global Services in Cluster Mesh).</li>
  <li>Service Awareness: Cilium can provide deeper visibility into service-to-service traffic flows by using Hubble, its observability platform. Hubble allows operators to see how services are discovered and how traffic flows between them in real time, making it easier to debug network issues or monitor service-level performance.</li>
</ul>

<p>DNS Resolution Example:</p>
<ul>
  <li>When a pod queries a service (e.g., <code class="language-plaintext highlighter-rouge">myapp.default.svc.cluster.local</code>), Cilium captures the DNS request and resolves it via CoreDNS.</li>
  <li>If the service spans multiple clusters (in the case of Cluster Mesh), Cilium returns the correct IP of the service, potentially in a remote cluster, using DNS-based load balancing.</li>
</ul>

<h3 id="shared-ingress">Shared Ingress</h3>

<p>Now let’s explore the concept of configuring the NGINX ingress controller to balance traffic across all available pods deployed across multiple Kubernetes clusters, interconnected via Cilium Cluster Mesh. A key aspect of this discussion will be how <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> help streamline traffic routing and enable enhanced visibility of network traffic in the cluster.</p>

<p>By default, most Kubernetes ingress controllers route traffic to services by directly using the list of endpoints (i.e., pod IPs) associated with a service. This allows traffic to bypass the Kubernetes service IP and directly reach the pods, optimizing performance and minimizing bottlenecks. However, this approach can be limiting when working with shared services across multiple clusters in a Cilium Cluster Mesh:</p>

<ul>
  <li>If the deployment is scaled down in one cluster, the ingress controller will see that no pod endpoints are available in the local cluster, and it will fail to route traffic correctly, causing the application to become unavailable.</li>
  <li>Traditional ingress controllers like Traefik rely entirely on endpoints, meaning they can’t route traffic to other clusters when no local endpoints exist.</li>
</ul>

<h4 id="nginx-ingress-controller-and-shared-services">NGINX Ingress Controller and Shared Services</h4>

<p>The NGINX Ingress Controller, however, offers a solution to this problem through the use of the <code class="language-plaintext highlighter-rouge">nginx.ingress.kubernetes.io/service-upstream</code> annotation. This annotation configures the ingress controller to route traffic to the service IP instead of directly to the pod IPs (endpoints). In a multi-cluster setup using Cilium Cluster Mesh, this feature is particularly valuable because it allows the NGINX ingress controller to balance traffic across services running in different clusters, even when no local pod endpoints exist.</p>

<h4 id="role-of-ciliumendpoints-in-shared-ingress">Role of <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> in Shared Ingress</h4>

<p><code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> are an essential part of Cilium’s architecture, providing detailed metadata about the state of pods and their networking configuration. Each pod is represented as a <code class="language-plaintext highlighter-rouge">CiliumEndpoint</code> object, which stores critical information about the pod’s identity, IP addresses, policies, and connection status. Cilium uses these objects to efficiently manage traffic routing and enforce network security policies.</p>

<p>In the context of shared ingress and NGINX, <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> enhance visibility and provide deeper control over pod-to-pod and service-to-service communication, especially in a multi-cluster environment.</p>

<h4 id="key-points-about-ciliumendpoints">Key Points About <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code>:</h4>

<ul>
  <li>Network Awareness: <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> provide a rich set of metadata about each pod’s networking state, enabling advanced traffic routing decisions based on security policies, IP management, and connectivity status.</li>
  <li>Endpoint Visibility: Unlike traditional Kubernetes endpoints that only expose basic IP addresses, <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> offer more granular insight into the pod’s status, facilitating more efficient traffic routing and policy enforcement across clusters.</li>
  <li>Cross-Cluster Integration: Cilium Cluster Mesh can use <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> to track the network state of pods across different clusters, ensuring that NGINX can balance traffic to services running in other clusters, even when local endpoints are unavailable.</li>
</ul>

<p>By leveraging <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code>, Cilium’s networking layer can provide ingress controllers with enhanced traffic intelligence. This is particularly useful when dealing with cross-cluster traffic routing, as <code class="language-plaintext highlighter-rouge">CiliumEndpoints</code> ensure that each cluster is aware of pod and service availability in other clusters, further optimizing the way ingress controllers route traffic.</p>

<h2 id="conclusion">Conclusion</h2>

<p>This article has provided a high-level overview of the capabilities and advantages of using Cilium Cluster Mesh within Kubernetes environments. By leveraging the cutting-edge eBPF technology, Cilium not only simplifies multi-cluster networking but also enhances security and observability across clusters.</p>

<p>While today’s discussion focused on the theoretical framework and potential benefits, a forthcoming post will delve into the practical aspects. We will provide a step-by-step guide (with accompanying code) on the actual implementation and a live demonstration of Cilium Cluster Mesh in action. This upcoming post will ensure you have the hands-on knowledge and tools to effectively deploy Cilium Cluster Mesh, empowering you to fully harness its capabilities in your own Kubernetes deployments.</p>

<p>Stay tuned for our next installment, where we’ll transition from theory to practice, demonstrating the tangible impacts of Cilium’s advanced networking features in real-world scenarios.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="cilium" /><category term="clustermesh" /><category term="kubernetes" /><category term="multicluster" /><category term="devops" /><category term="cluster" /><category term="gitops" /><summary type="html"><![CDATA[Cluster Mesh with Cilium Overview]]></summary></entry><entry><title type="html">Vagrant + RKE2 + Cilium</title><link href="https://mitchmurphy.io/vagrant/" rel="alternate" type="text/html" title="Vagrant + RKE2 + Cilium" /><published>2024-06-09T00:00:00-04:00</published><updated>2024-06-09T00:00:00-04:00</updated><id>https://mitchmurphy.io/vagrant</id><content type="html" xml:base="https://mitchmurphy.io/vagrant/"><![CDATA[<h1 id="use-vagrant-to-provision-and-install-rke2-and-cilium">Use Vagrant to provision and install RKE2 and Cilium</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Use Vagrant to provision and install RKE2 and Cilium</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2024-06-09</span>
</code></pre></div></div>
<ul>
  <li><a href="#use-vagrant-to-provision-and-install-rke2-and-cilium">Use Vagrant to provision and install RKE2 and Cilium</a>
    <ul>
      <li><a href="#introduction">Introduction</a>
        <ul>
          <li><a href="#pros">Pros</a></li>
          <li><a href="#cons">Cons</a></li>
        </ul>
      </li>
      <li><a href="#provision-rke2">Provision RKE2</a>
        <ul>
          <li><a href="#benefits-of-using-vagrant-for-local-kubernetes-cluster">Benefits of Using Vagrant for Local Kubernetes Cluster:</a></li>
          <li><a href="#challenges">Challenges:</a></li>
        </ul>
      </li>
      <li><a href="#installation">Installation</a>
        <ul>
          <li><a href="#install-virtualization-provider">Install Virtualization Provider</a></li>
          <li><a href="#install-vagrant">Install Vagrant</a></li>
          <li><a href="#install-required-plugins-optional">Install Required Plugins (Optional)</a></li>
          <li><a href="#ensure-kernel-modules-for-virtualization-are-loaded">Ensure Kernel Modules for Virtualization are Loaded</a></li>
          <li><a href="#verify-installation">Verify Installation</a></li>
        </ul>
      </li>
      <li><a href="#configuration">Configuration</a></li>
    </ul>
  </li>
</ul>

<h2 id="introduction">Introduction</h2>

<p>Vagrant is an open-source tool designed to create and manage virtualized development environments. It allows developers to define and configure lightweight, reproducible, and portable virtual environments using a simple configuration file called a Vagrantfile. Vagrant integrates with various virtualization technologies like VirtualBox, VMware, and Docker, enabling users to set up and tear down development environments quickly and consistently. By using Vagrant, developers can ensure that their development environments are identical across different machines, reducing the “works on my machine” problem and facilitating collaboration among team members.</p>

<h3 id="pros">Pros</h3>

<ul>
  <li>Consistency and Reproducibility: Vagrant ensures that development environments are consistent across all team members’ machines, reducing discrepancies between development, testing, and production environments.</li>
  <li>Easy Setup and Configuration: With Vagrant, setting up a development environment is straightforward and automated, often requiring just a single command to get started.</li>
  <li>Isolation: Vagrant environments are isolated from the host system, minimizing the risk of conflicts with other applications and dependencies.</li>
  <li>Flexibility: Vagrant supports multiple virtualization providers and can be used with various provisioning tools like Ansible, Puppet, and Chef, providing flexibility in how environments are configured and managed.</li>
</ul>

<h3 id="cons">Cons</h3>

<ul>
  <li>Resource Intensive: Running multiple Vagrant environments can be resource-intensive, requiring significant CPU, memory, and disk space, especially on less powerful machines.</li>
  <li>Learning Curve: For new users, there can be a learning curve associated with understanding Vagrant and its configuration files, particularly when integrating with complex provisioning tools.</li>
  <li>Performance Overheads: Virtualized environments may introduce performance overheads compared to running applications natively on the host machine, which can impact development and testing speeds.</li>
  <li>Dependency on Virtualization Providers: Vagrant relies on external virtualization providers, and any issues or limitations with these providers can affect the performance and reliability of Vagrant environments.</li>
</ul>

<h2 id="provision-rke2">Provision RKE2</h2>

<p>Vagrant can be utilized to configure and provision a local Kubernetes cluster by automating the setup of virtual machines (VMs) that act as the nodes of the cluster. Here’s a step-by-step outline of how this can be achieved:</p>

<ol>
  <li>Define Vagrantfile:
    <ul>
      <li>Create a Vagrantfile to define the configuration for the VMs. This file specifies the number of VMs, their resources (CPU, memory, etc.), and the base image to use.</li>
      <li>Example configuration might include one VM as the master node and two or more VMs as worker nodes.</li>
    </ul>
  </li>
  <li>Provisioning the VMs:
    <ul>
      <li>Use provisioning scripts or configuration management tools (like Ansible, Puppet, or Chef) within the Vagrantfile to install necessary dependencies on the VMs. This typically includes Docker, kubeadm, kubectl, and kubelet.</li>
      <li>The provisioning script also sets up networking between the VMs to ensure they can communicate with each other.</li>
    </ul>
  </li>
  <li>Initialize the Kubernetes Master Node:
    <ul>
      <li>After the VMs are up and running, SSH into the master node and run kubeadm init to initialize the Kubernetes master. This command sets up the control plane and generates a command (with a token) to join the worker nodes to the cluster.</li>
    </ul>
  </li>
  <li>Configure kubectl:
    <ul>
      <li>Configure the kubectl command-line tool on the master node to interact with the cluster by copying the kubeconfig file to the appropriate location.</li>
    </ul>
  </li>
  <li>Join Worker Nodes:
    <ul>
      <li>SSH into each worker node and run the join command provided by kubeadm init. This command joins the worker nodes to the Kubernetes cluster, making them part of the cluster’s node pool.</li>
    </ul>
  </li>
  <li>Network Setup:
    <ul>
      <li>Deploy a network plugin (such as Flannel, Calico, or Weave) to handle pod networking. This can be done by applying the relevant YAML file using kubectl apply -f <network-plugin.yaml>.</network-plugin.yaml></li>
    </ul>
  </li>
  <li>Verify the Cluster:
  -Once all nodes are joined and the network plugin is configured, verify the cluster status by running kubectl get nodes on the master node. All nodes should be in a “Ready” state.</li>
</ol>

<h3 id="benefits-of-using-vagrant-for-local-kubernetes-cluster">Benefits of Using Vagrant for Local Kubernetes Cluster:</h3>

<ul>
  <li>Reproducibility: Easily recreate the cluster environment for consistent development and testing.</li>
  <li>Isolation: The cluster runs in isolated VMs, preventing interference with the host system.</li>
  <li>Automation: Automated setup reduces manual configuration time and potential errors.</li>
</ul>

<h3 id="challenges">Challenges:</h3>

<ul>
  <li>Resource Consumption: Multiple VMs can be resource-intensive.</li>
  <li>Configuration Complexity: Initial setup and configuration can be complex, especially for users unfamiliar with Vagrant or Kubernetes.</li>
</ul>

<h2 id="installation">Installation</h2>

<p>For the purposes of this tutorial, we will be using a Debian based system (Pop!_OS). To run Vagrant on a Debian-based system, you need to ensure that several prerequisites are met. Here is a comprehensive list of the prerequisites and steps to get Vagrant up and running:</p>

<h3 id="install-virtualization-provider">Install Virtualization Provider</h3>

<p>Vagrant requires a virtualization provider to create and manage virtual machines. The most commonly used provider is VirtualBox, but you can also use others like VMware or Docker. Here, we will focus on VirtualBox.</p>

<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="go">sudo apt update
sudo apt install -y virtualbox
</span></code></pre></div></div>

<h3 id="install-vagrant">Install Vagrant</h3>

<p>Next, you need to install Vagrant. You can download the .deb package from the official Vagrant website or use the package manager.</p>

<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="go">curl -fsSL https://apt.releases.hashicorp.com/gpg | sudo apt-key add -
</span><span class="gp">sudo apt-add-repository "deb [arch=amd64] https://apt.releases.hashicorp.com $</span><span class="o">(</span>lsb_release <span class="nt">-cs</span><span class="o">)</span> main<span class="s2">"
</span><span class="go">sudo apt update
sudo apt install -y vagrant
</span></code></pre></div></div>

<p>There are a few other packages that you will need:</p>

<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="go">sudo apt update &amp;&amp; sudo apt install -y libvirt-dev qemu-kvm libvirt-daemon-system bridge-utils virtinst libvirt-daemon virt-manager libvirt-doc ruby-libvirt qemu libvirt-clients ebtables dnsmasq-base libxslt-dev libxml2-dev zlib1g-dev ruby-dev libguestfs-tools
</span></code></pre></div></div>

<h3 id="install-required-plugins-optional">Install Required Plugins (Optional)</h3>

<p>Depending on your use case, you might need to install additional Vagrant plugins. For example, if you’re using a different provider or need specific functionalities.</p>

<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="go">PLUGINS=vagrant-vboxmanage vagrant-vbguest vagrant-libvirt vagrant-reload
</span><span class="gp">for PLUGIN in $</span>PLUGINS<span class="p">;</span> <span class="k">do</span>
<span class="gp">  vagrant plugin install $</span>PLUGIN
<span class="go">done
</span></code></pre></div></div>

<h3 id="ensure-kernel-modules-for-virtualization-are-loaded">Ensure Kernel Modules for Virtualization are Loaded</h3>

<p>For VirtualBox to work correctly, ensure that the necessary kernel modules are loaded.</p>

<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="go">sudo modprobe vboxdrv
sudo modprobe vboxnetflt
sudo modprobe vboxnetadp
</span></code></pre></div></div>

<h3 id="verify-installation">Verify Installation</h3>

<p>To confirm that Vagrant and VirtualBox are installed correctly, you can check their versions.</p>

<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="go">vagrant --version
vboxmanage --version
</span></code></pre></div></div>

<h2 id="configuration">Configuration</h2>

<p>I have prepared a simple <code class="language-plaintext highlighter-rouge">Vagrantfile</code> for you to get started with standing up an RKE2 v1.30.1 cluster, Cilium, K9s and Helm. Stay tuned for more details regarding this configuration (this will more than likely be reflected in the README of the repository). <a href="https://github.com/gaianetes/kubula/blob/feature/packer-rocky/infrastructure/vagrant/Vagrantfile">Link</a> to repository.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="cilium" /><category term="devops" /><category term="cluster" /><category term="vagrant" /><summary type="html"><![CDATA[Use Vagrant to provision and install RKE2 and Cilium]]></summary></entry><entry><title type="html">Cilium and Istio Harmony</title><link href="https://mitchmurphy.io/cilium-and-istio-harmony/" rel="alternate" type="text/html" title="Cilium and Istio Harmony" /><published>2024-03-16T00:00:00-04:00</published><updated>2024-03-16T00:00:00-04:00</updated><id>https://mitchmurphy.io/cilium-and-istio-harmony</id><content type="html" xml:base="https://mitchmurphy.io/cilium-and-istio-harmony/"><![CDATA[<h1 id="update-cilium-to-work-with-istio-and-create-a-self-signed-certificate-for-istio">Update Cilium to work with Istio and create a self-signed certificate for Istio</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Update Cilium to work with Istio and create a self-signed certificate for Istio</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2024-03-16</span>
</code></pre></div></div>

<ul>
  <li><a href="#update-cilium-to-work-with-istio-and-create-a-self-signed-certificate-for-istio">Update Cilium to work with Istio and create a self-signed certificate for Istio</a>
    <ul>
      <li><a href="#introduction">Introduction</a></li>
      <li><a href="#pre-requisites">Pre-requisites</a></li>
      <li><a href="#update-cilium-chart">Update Cilium chart</a></li>
      <li><a href="#create-istio-namespace">Create Istio Namespace</a></li>
      <li><a href="#create-self-signed-certificate">Create self-signed certificate</a></li>
    </ul>
  </li>
</ul>

<h2 id="introduction">Introduction</h2>

<p>In this post we are going to update Cilium to work with Istio and create self-signed certificates for Istio.</p>

<p>As discussed in my previous <a href="https://mitchmurphy.io/cilium-rke2/">post</a>, Cilium, when replaceing <a href="https://docs.cilium.io/en/stable/network/kubernetes/kubeproxy-free/">kube-proxy</a>, provides very powerful features which can increase performance for large Kubernetes clusters. While Cilium does offer a service mesh (with mTLS), it is still in beta and other solutions such as Istio are quite mature and offer a lot of capabilities.</p>

<p>When utilizing alternative networking infrastructure, the underlying Cilium eBPF implementation that replaces kube-proxy may inadvertently reveal itself and lead to unexpected behaviors. This becomes evident when attempting to integrate Istio service mesh with Cilium’s kube-proxy replacement, as the default replacement of kube-proxy can disrupt Istio’s functionality.</p>

<h2 id="pre-requisites">Pre-requisites</h2>

<ul>
  <li><a href="https://rke2.io/">RKE2</a></li>
  <li><a href="https://cilium.io/">Cilium</a></li>
  <li><a href="https://istio.io/">Istio</a></li>
  <li><a href="https://helm.sh/">Helm</a></li>
  <li><a href="https://www.gnu.org/software/make/">Make</a></li>
  <li><a href="https://kubernetes.io/docs/tasks/tools/install-kubectl/">Kubectl</a></li>
</ul>

<p>This blog <a href="https://www.solo.io/blog/istio-cilium-kube-proxy-replacement/">post</a> had a profound impact on the creation of the one you’re reading now.</p>

<h2 id="update-cilium-chart">Update Cilium chart</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>helm upgrade cilium <span class="se">\</span>
    <span class="nt">--namespace</span> kube-system <span class="se">\</span>
    <span class="nt">--set</span> ipam.mode<span class="o">=</span>kubernetes <span class="se">\</span>
    <span class="nt">--set</span> socketLB.hostNamespaceOnly<span class="o">=</span><span class="nb">true</span>
</code></pre></div></div>

<h2 id="create-istio-namespace">Create Istio Namespace</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl create namespace istio-system
</code></pre></div></div>

<p><em>Note</em> that you can also specify the creation of the namespace in the below script.</p>

<h2 id="create-self-signed-certificate">Create self-signed certificate</h2>

<p>For this step we are going to use a few scripts from the istio repository. These tools can be found <a href="../tools/">here</a>. The first step is to create the namespace and then generate the self-signed certificate that Istio will be using (here we are assuming 3 clusters). The following script will create the certificates and then create the secrets in each cluster (you must have the <code class="language-plaintext highlighter-rouge">kubeconfig</code> for each cluster in order to run the script).</p>

<p>You can find the scripts at the following location: <a href="../scripts/istio">istio-tools</a>, the specific script is <a href="../scripts/istio/make-certs.sh">make-certs.sh</a>.</p>

<p><em>TODO</em>: real world example(s)</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="cilium" /><category term="devops" /><category term="cluster" /><category term="istio" /><category term="tls" /><summary type="html"><![CDATA[Update Cilium to work with Istio and create a self-signed certificate for Istio.]]></summary></entry><entry><title type="html">Bootstrap cluster with Flux: the GitOps way</title><link href="https://mitchmurphy.io/fluxcd/" rel="alternate" type="text/html" title="Bootstrap cluster with Flux: the GitOps way" /><published>2022-12-27T00:00:00-05:00</published><updated>2022-12-27T00:00:00-05:00</updated><id>https://mitchmurphy.io/fluxcd</id><content type="html" xml:base="https://mitchmurphy.io/fluxcd/"><![CDATA[<h1 id="bootstrap-cluster-with-flux-the-gitops-way">Bootstrap cluster with Flux: the GitOps way</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="na">Bootstrap cluster with Flux</span><span class="pi">:</span> <span class="s">the GitOps way</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2023-12-27</span>
</code></pre></div></div>

<hr />

<ul>
  <li><a href="#bootstrap-cluster-with-flux-the-gitops-way">Bootstrap cluster with Flux: the GitOps way</a></li>
  <li><a href="#introduction">Introduction</a></li>
  <li><a href="#prerequisites">Prerequisites</a></li>
  <li><a href="#install-flux">Install Flux</a>
    <ul>
      <li><a href="#bootstrap-cluster-with-flux">Bootstrap cluster with Flux</a></li>
    </ul>
  </li>
  <li><a href="#components">Components</a></li>
  <li><a href="#conclusion">Conclusion</a></li>
</ul>

<h1 id="introduction">Introduction</h1>

<p>What is GitOps? GitOps is a way to do Continuous Delivery, it works by using Git as a single source of truth for declarative infrastructure and applications. With GitOps, we can make changes to our infrastructure and applications by making pull requests against our Git repository. These changes are then automatically applied to our cluster by a GitOps operator. This allows us to manage our infrastructure and applications in a declarative way, using the same Git workflow that we use for application code.</p>

<p>Flux CD is an open-source continuous delivery (CD) tool designed for Kubernetes applications. It automates the deployment and lifecycle management of applications running on Kubernetes clusters. Flux CD focuses on ensuring that the desired state of your Kubernetes resources matches the actual state, thus enabling GitOps practices.</p>

<p>Key features and concepts of Flux CD include:</p>

<ol>
  <li><strong>GitOps</strong>: Flux CD follows the GitOps operational model, where the desired state of your Kubernetes cluster is declared in a Git repository. Changes to the cluster are made by updating the Git repository, and Flux CD automatically applies those changes to the cluster, ensuring that the actual state converges with the declared state.</li>
  <li><strong>Automation</strong>: Flux CD automates the deployment of applications by synchronizing the Kubernetes manifests stored in a Git repository with the resources running in the cluster. This allows for a declarative approach to managing infrastructure and applications.</li>
  <li><strong>Continuous Delivery</strong>: Flux CD is commonly used for implementing continuous delivery pipelines on Kubernetes. When changes are pushed to the Git repository, Flux CD automatically detects them and triggers the deployment process.</li>
  <li><strong>Helm Support</strong>: Flux CD has built-in support for Helm charts, a package manager for Kubernetes applications. It can automatically sync and apply changes to Helm releases based on the charts stored in the Git repository.</li>
  <li><strong>Multi-Environment Support</strong>: Flux CD supports multi-environment setups, allowing you to manage and deploy applications across different clusters or namespaces.</li>
  <li><strong>Notifications</strong>: Flux CD provides notifications and alerts to keep users informed about the state of deployments and any issues that may arise.</li>
</ol>

<p>Flux CD is often used in conjunction with other tools and practices that adhere to the GitOps methodology, such as version control systems (like Git), CI/CD pipelines, and Kubernetes operators.</p>

<h1 id="prerequisites">Prerequisites</h1>

<p>Before you begin this guide, you’ll need the following:</p>

<ol>
  <li>A Kubernetes cluster running RKE2</li>
  <li><a href="https://fluxcd.io/flux/cmd/">Flux CLI</a></li>
  <li>Flux installed on your cluster</li>
  <li>A GitHub repository to store your cluster configuration</li>
</ol>

<h1 id="install-flux">Install Flux</h1>

<p>We will be using Flux CD to bootstrap our cluster. If you haven’t already, you will need to install Flux CD on your cluster. You can find a guide on how to do this <a href="https://mitchmurphy.dev/posts/fluxcd/">here</a>.</p>

<h2 id="bootstrap-cluster-with-flux">Bootstrap cluster with Flux</h2>

<p>Once you have Flux CD installed, you are ready to boostrap your cluster. We will be using the Flux CLI to bootstrap our cluster. The Flux CLI is a command-line tool that allows you to interact with Flux CD. It can be used to create and manage Flux CD resources, such as Git repositories, Helm releases, and Kubernetes resources. We will be following this <a href="https://fluxcd.io/flux/cmd/flux_bootstrap_github/">guide</a>.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">flux bootstrap github \</span>
    <span class="s">--owner=mkm29 \</span>
    <span class="s">--repository=kubula \</span>
    <span class="s">—-path=clusters/mgmt \</span>
    <span class="s">--token-auth \</span>
    <span class="s">--personal \</span>
    <span class="s">--branch=main</span>
</code></pre></div></div>

<p>The bootstrap github command creates the GitHub repository if it doesn’t exists and commits the Flux manifests to the specified branch. Then it configures the target cluster to synchronize with that repository.</p>

<h1 id="components">Components</h1>

<p>Flux CD consists of several components that work together to provide the desired functionality. These components include:</p>

<ol>
  <li><strong>Flux</strong>: The core component of Flux CD, Flux is a Kubernetes operator that runs on the cluster and manages the deployment of applications. It monitors the Git repository for changes and automatically applies them to the cluster.</li>
  <li><strong>Helm Operator</strong>: The Helm Operator is a Kubernetes operator that manages Helm releases. It can automatically sync and apply changes to Helm releases based on the charts stored in the Git repository.</li>
  <li><strong>Memcached</strong>: Memcached is a distributed memory object caching system that is used by Flux CD to store and retrieve data.</li>
  <li><strong>Notification Controller</strong>: The Notification Controller is a Kubernetes controller that sends notifications and alerts to users about the state of deployments and any issues that may arise.</li>
  <li><strong>Image Automation Controller</strong>: The Image Automation Controller is a Kubernetes controller that automates the deployment of container images. It can automatically pull new images from a registry and update the corresponding Kubernetes resources.</li>
  <li><strong>Kustomize Controller</strong>: The Kustomize Controller is a Kubernetes controller that manages Kustomize resources. It can automatically sync and apply changes to Kustomize resources based on the manifests stored in the Git repository.</li>
  <li><strong>Source Controller</strong>: The Source Controller is a Kubernetes controller that manages Git repositories. It can automatically sync and apply changes to Git repositories based on the manifests stored in the Git repository.</li>
</ol>

<p>We are going to use Flux CD to bootstrap a minimal set of Kubernetes components, including a Prometheus monitoring stack, persistent storage via Longhorn and Argo CD. The structure can be found <a href="https://github.com/gaianetes/kubula/tree/main/clusters/mgmt">here</a></p>

<h1 id="conclusion">Conclusion</h1>

<p>In this guide, we have learned how to bootstrap a Kubernetes cluster with Flux CD using GitOps. We have also learned about the key features and concepts of Flux CD, as well as its components. We have also learned how to use the Flux CLI to bootstrap our cluster. Finally, we have learned how to use Flux CD to bootstrap a minimal set of Kubernetes components, including a Prometheus monitoring stack, persistent storage via Longhorn and Argo CD.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="flux" /><category term="devops" /><category term="cluster" /><category term="gitops" /><summary type="html"><![CDATA[Bootstrap a Kubernetes cluster with Flux CD using GitOps]]></summary></entry><entry><title type="html">Adding Persistent Storage to RKE2 with Longhorn</title><link href="https://mitchmurphy.io/longhorn/" rel="alternate" type="text/html" title="Adding Persistent Storage to RKE2 with Longhorn" /><published>2022-12-27T00:00:00-05:00</published><updated>2022-12-27T00:00:00-05:00</updated><id>https://mitchmurphy.io/longhorn</id><content type="html" xml:base="https://mitchmurphy.io/longhorn/"><![CDATA[<h1 id="adding-persistent-storage-to-rke2-with-longhorn">Adding Persistent Storage to RKE2 with Longhorn</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Adding Persistent Storage to RKE2 with Longhorn</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2023-12-27</span>
</code></pre></div></div>

<hr />

<ul>
  <li><a href="#adding-persistent-storage-to-rke2-with-longhorn">Adding Persistent Storage to RKE2 with Longhorn</a></li>
  <li><a href="#introduction">Introduction</a></li>
  <li><a href="#prerequisites">Prerequisites</a></li>
  <li><a href="#install-longhorn">Install Longhorn</a></li>
  <li><a href="#configure-longhorn">Configure Longhorn</a>
    <ul>
      <li><a href="#virtual-hard-disk">Virtual Hard Disk</a></li>
    </ul>
  </li>
  <li><a href="#conclusion">Conclusion</a></li>
</ul>

<h1 id="introduction">Introduction</h1>

<p>What is Longhorn? Longhorn refers to a project that provides persistent storage for Kubernetes. Longhorn aims to simplify and enhance the management of persistent storage in Kubernetes clusters. It is an open-source distributed block storage system that can be deployed as a containerized application.</p>

<p>Some key features of Longhorn include:</p>

<ol>
  <li><strong>Distributed Storage</strong>: Longhorn distributes block storage across multiple nodes in a Kubernetes cluster, providing redundancy and fault tolerance.</li>
  <li><strong>Snapshot and Backup</strong>: It supports snapshots, allowing you to capture the state of your persistent volumes at a specific point in time. Additionally, Longhorn includes features for backup and restore operations.</li>
  <li><strong>Replication and Synchronization</strong>: Longhorn replicates data across nodes to ensure data integrity and provides mechanisms for data synchronization.</li>
  <li><strong>User Interface</strong>: Longhorn includes a user-friendly web-based UI that allows users to manage and monitor their storage resources easily.</li>
  <li><strong>Kubernetes Native</strong>: Longhorn is designed to work seamlessly with Kubernetes, integrating into the Kubernetes control plane and leveraging custom resources to define and manage persistent volumes.</li>
</ol>

<p>It’s worth noting that the landscape of Kubernetes storage solutions may evolve, and new developments may have occurred since my last update. Therefore, I recommend checking the official Longhorn project documentation or other reliable sources for the latest information on Longhorn and its features.</p>

<h1 id="prerequisites">Prerequisites</h1>

<p>Before you begin this guide, you’ll need the following:</p>

<ol>
  <li>A Kubernetes cluster running RKE2</li>
  <li>Flux CD installed on your cluster</li>
  <li>A GitHub repository to store your cluster configuration</li>
  <li>Storage provisioned, mounted and formatted on each node in your cluster
    <ul>
      <li>For this guide, I will be attaching a <code class="language-plaintext highlighter-rouge">Virtual Hard Disk</code> to each node/virtual machine in Hyper-V, mounted at <code class="language-plaintext highlighter-rouge">/mnt/storage</code></li>
      <li>After attaching the VHD to each node, you will need to format the disk with a filesystem. For this guide, I will be using <code class="language-plaintext highlighter-rouge">ext4</code></li>
      <li>Stay tuned as I will be writing a guide on how to automate this process using Ansible</li>
    </ul>
  </li>
</ol>

<h1 id="install-longhorn">Install Longhorn</h1>

<p>We will be using Flux CD to install Longhorn on our cluster. If you haven’t already, you will need to install Flux CD on your cluster. You can find a guide on how to do this <a href="https://mitchmurphy.dev/fluxcd/">here</a>. Once you have Flux CD installed, you will need to create a <code class="language-plaintext highlighter-rouge">HelmRepository</code> resource to point to the Longhorn Helm chart as well as a <code class="language-plaintext highlighter-rouge">HelmRelease</code> resource to install Longhorn on your cluster. Please see the structure in this <a href="https://github.com/gaianetes/kubula">repo</a></p>

<h1 id="configure-longhorn">Configure Longhorn</h1>

<h2 id="virtual-hard-disk">Virtual Hard Disk</h2>

<p>First, we need to attach a <code class="language-plaintext highlighter-rouge">Virtual Hard Disk</code> to each node/virtual machine in Hyper-V. This will be used as the storage for Longhorn. To do this, you will need to:</p>

<ol>
  <li>Create a <code class="language-plaintext highlighter-rouge">Virtual Hard Disk</code> in Hyper-V (follow this <a href="https://www.altaro.com/hyper-v/hyper-v-attach-existing-virtual-disk/">guide</a>)</li>
  <li>Attach it to each node/virtual machine in your cluster</li>
  <li>Format/partition the disk with a filesystem. For this guide, I will be using <code class="language-plaintext highlighter-rouge">ext4</code></li>
  <li>Mount the disk to <code class="language-plaintext highlighter-rouge">/mnt/storage</code> on each node/virtual machine in your cluster. Make sure to add an entry to <code class="language-plaintext highlighter-rouge">/etc/fstab</code> so that the disk is mounted on boot
    <ul>
      <li><code class="language-plaintext highlighter-rouge">echo "/dev/sdb1 /mnt/storage ext4 defaults 0 0" &gt;&gt; /etc/fstab</code></li>
    </ul>
  </li>
  <li>You can find a guide on how to do this <a href="https://www.tecmint.com/create-new-ext4-file-system-partition-in-linux/">here</a>.</li>
</ol>

<p>As we will be mounting our storage to <code class="language-plaintext highlighter-rouge">/mnt/storage</code> you must set the <code class="language-plaintext highlighter-rouge">defaultSettings.defaultDataPath</code> to <code class="language-plaintext highlighter-rouge">/mnt/storage</code> in the <code class="language-plaintext highlighter-rouge">HelmRelease</code> resource. This will ensure that Longhorn will use the storage we have provisioned on each node in our cluster.</p>

<p><em>Note</em>: that this will create a default <code class="language-plaintext highlighter-rouge">StorageClass</code> on our Kubernetes cluster. This means that you do not need to specify the <code class="language-plaintext highlighter-rouge">StorageClass</code> when you create <code class="language-plaintext highlighter-rouge">PersistentVolumeClaims</code>, as the default <code class="language-plaintext highlighter-rouge">StorageClass</code> will be used to provision the <code class="language-plaintext highlighter-rouge">PersistentVolume</code>.</p>

<h1 id="conclusion">Conclusion</h1>

<p>In this guide, we have installed Longhorn on our RKE2 cluster using Flux CD. We have also configured Longhorn to use the storage we have provisioned on each node in our cluster. This means that we can now create <code class="language-plaintext highlighter-rouge">PersistentVolumeClaims</code> without specifying the <code class="language-plaintext highlighter-rouge">StorageClass</code> as the default <code class="language-plaintext highlighter-rouge">StorageClass</code> will be used to provision the <code class="language-plaintext highlighter-rouge">PersistentVolume</code>.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="longhorn" /><category term="devops" /><category term="cluster" /><category term="storage" /><category term="persistence" /><summary type="html"><![CDATA[Configure Longhorn to provide persistent storage to RKE2 clusters using Flux CD]]></summary></entry><entry><title type="html">ArgoCD RBAC</title><link href="https://mitchmurphy.io/argocd-rbac/" rel="alternate" type="text/html" title="ArgoCD RBAC" /><published>2022-12-03T00:00:00-05:00</published><updated>2022-12-03T00:00:00-05:00</updated><id>https://mitchmurphy.io/argocd-rbac</id><content type="html" xml:base="https://mitchmurphy.io/argocd-rbac/"><![CDATA[<h1 id="how-to-guide-configuring-argocd-rbac">How to Guide: Configuring ArgoCD RBAC</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Configuring ArgoCD RBAC</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2023-12-03</span>
</code></pre></div></div>

<hr />

<ul>
  <li><a href="#how-to-guide-configuring-argocd-rbac">How to Guide: Configuring ArgoCD RBAC</a>
    <ul>
      <li><a href="#introduction">Introduction</a></li>
      <li><a href="#prerequisites">Prerequisites</a></li>
      <li><a href="#add-cluster">Add Cluster</a></li>
      <li><a href="#rbac-configuration">RBAC Configuration</a></li>
      <li><a href="#deploying-application">Deploying Application</a></li>
    </ul>
  </li>
</ul>

<h2 id="introduction">Introduction</h2>

<p>ArgoCD is a great tool for managing your Kubernetes clusters. It allows you to deploy applications to your clusters and keep them in sync. It also allows you to manage your clusters and applications through a GitOps workflow. This means that you can manage your clusters and applications through Git and have ArgoCD keep them in sync. This is great for managing multiple clusters and applications. We can utilize ArgoCD for managing deployments to multiple clusters by multiple teams. This is where RBAC comes in. RBAC stands for Role Based Access Control. It allows us to define roles and permissions for users and groups. This allows us to control who can access what resources in our clusters. This is great for managing access to our clusters and applications.</p>

<h2 id="prerequisites">Prerequisites</h2>

<ul>
  <li>Kubernetes Cluster(s)</li>
  <li>ArgoCD</li>
  <li>Helm</li>
  <li>Keycloak</li>
</ul>

<h2 id="add-cluster">Add Cluster</h2>

<p>First, lets add a new cluster to ArgoCD. For this, we need to use the CLI:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl -n argocd port-forward svc/argocd-server 8080:80</span>
<span class="s">argocd login localhost:8080 --username admin --password &lt;PASSWD&gt; --insecure</span>
</code></pre></div></div>

<p>Now, we can add our cluster (the name must be the name of the context in your kubeconfig):</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">argocd cluster add &lt;CLUSTER_NAME&gt;</span>
</code></pre></div></div>

<p>We will be using the second cluster that we previously <a href="https://mitchmurphy.io/cilium-rke2/">created</a> and added to our Cilium cluster mesh (<code class="language-plaintext highlighter-rouge">smig-cluster2</code>).</p>

<h2 id="rbac-configuration">RBAC Configuration</h2>

<p>First, follow this <a href="https://argo-cd.readthedocs.io/en/stable/operator-manual/user-management/keycloak/">guide</a> on how to configure ArgoCD to use Keycloak for authentication. This will allow us to use Keycloak for authentication and authorization. You must create a group named <code class="language-plaintext highlighter-rouge">smig2-team</code> and then add user(s) to this group. This will be the group that we will use for RBAC.</p>

<p>Now we need to update the ArgoCD Helm chart to enable RBAC. We can do this by specifying a values file:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cat &lt;&lt;EOF &gt; argocd-rbac-values.yaml</span>
<span class="na">configs</span><span class="pi">:</span>
  <span class="na">oidc.config</span><span class="pi">:</span> <span class="pi">|</span>
    <span class="s">name: SmigAdmins</span>
    <span class="s">issuer: https://auth.smigula.io/realms/smig/</span>
    <span class="s">clientID: argocd</span>
    <span class="s">clientSecret: $oidc.azuread.clientSecret</span>
    <span class="s">requestedIDTokenClaims:</span>
      <span class="s">groups:</span>
        <span class="s">essential: true</span>
    <span class="s">requestedScopes:</span>
      <span class="s">- openid</span>
      <span class="s">- profile</span>
      <span class="s">- email</span>
      <span class="s">- groups</span>
  <span class="na">rbac</span><span class="pi">:</span>
    <span class="s">policy.csv |</span>
      <span class="s">p, role:smig-admin, applications, *, */*, allow</span>
      <span class="s">p, role:smig-admin, clusters, *, smig-cluster2, allow</span>
      <span class="s">p, role:smig-admin, repositories, *, *, allow</span>
      <span class="s">p, role:smig-admin, logs, get, *, allow</span>
      <span class="s">p, role:smig-admin, exec, create, */*, allow</span>
      <span class="s">g, smig2-team, role:smig-admin</span>
<span class="s">EOF</span>
</code></pre></div></div>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm upgrade argocd argo/argo-cd -f argocd-rbac-values.yaml</span>
</code></pre></div></div>

<h2 id="deploying-application">Deploying Application</h2>

<p>Now, we can deploy an application to our secondary cluster using ArgoCD. We will be deploying the <a href="https://github.com/argoproj/argocd-example-apps/tree/master/helm-guestbook">guestbook</a>. First, we need to create a new project as an admin:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">argocd proj create smig2-team \</span>
  <span class="s">--description "Smigula Team 2" \</span>
  <span class="s">--dest https://192.168.7.31:6443,default \</span>
  <span class="s">--allow-cluster-resource \</span>
  <span class="s">--allow-namespaced-resource</span>
</code></pre></div></div>

<p>Now login to the ArgoCD web UI as a user in the <code class="language-plaintext highlighter-rouge">smig2-team</code> group. You should see the <code class="language-plaintext highlighter-rouge">smig2-team</code> project. Click on it and then click <code class="language-plaintext highlighter-rouge">New App</code>. Fill out the form with the following information:</p>

<ul>
  <li>Application Name: <code class="language-plaintext highlighter-rouge">guestbook</code></li>
  <li>Repository URL: <code class="language-plaintext highlighter-rouge">https://github.com/argoproj/argocd-example-apps.git</code></li>
  <li>Revision: <code class="language-plaintext highlighter-rouge">HEAD</code></li>
  <li>Path: <code class="language-plaintext highlighter-rouge">helm-guestbook</code></li>
</ul>

<p>For Destination, set cluster URL to <code class="language-plaintext highlighter-rouge">https://192.168.7.31:6443</code> and namespace to <code class="language-plaintext highlighter-rouge">default</code>. Click <code class="language-plaintext highlighter-rouge">Create</code>. Now, you should see the application in the <code class="language-plaintext highlighter-rouge">smig2-team</code> project. Click on it and then click <code class="language-plaintext highlighter-rouge">Sync</code>. This will deploy the application to the cluster. You can now access the application by port forwarding the service:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl port-forward svc/guestbook-ui 8080:80</span>
</code></pre></div></div>

<p>Now, you can access the application at <code class="language-plaintext highlighter-rouge">http://localhost:8080</code>. You can also access the application through the ArgoCD web UI by clicking on the application and then clicking <code class="language-plaintext highlighter-rouge">Open in new tab</code>. You should see the guestbook application. You can now make changes to the application and ArgoCD will keep it in sync. You can also add more users to the <code class="language-plaintext highlighter-rouge">smig2-team</code> group in Keycloak and they will be able to access the application.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rbac" /><category term="argocd" /><category term="devops" /><category term="cluster" /><category term="keycloak" /><summary type="html"><![CDATA[Howto guide for setting up ArgoCD RBAC]]></summary></entry><entry><title type="html">Boostrapping RKE2</title><link href="https://mitchmurphy.io/bootstrap-cluster/" rel="alternate" type="text/html" title="Boostrapping RKE2" /><published>2022-12-02T00:00:00-05:00</published><updated>2022-12-02T00:00:00-05:00</updated><id>https://mitchmurphy.io/bootstrap-cluster</id><content type="html" xml:base="https://mitchmurphy.io/bootstrap-cluster/"><![CDATA[<h1 id="how-to-guide-boostrapping-rke2-with-argocd-prometheus-and-cert-manager">How to Guide: Boostrapping RKE2 with ArgoCD, Prometheus, and Cert-Manager</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Boostrapping RKE2 with ArgoCD</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2023-12-02</span>
</code></pre></div></div>

<hr />

<h2 id="introduction">Introduction</h2>

<p>This guide will walk you through the steps to bootstrap an RKE2 cluster with ArgoCD. This guide assumes you have a working RKE2 cluster and ArgoCD instance. If you do not have these, please refer to my previous post on installing RKE2 with Cilium: <a href="https://mitchmurphy.io/cilium-rke2/">here</a></p>

<h2 id="table-of-contents">Table of Contents</h2>

<ul>
  <li><a href="#how-to-guide-boostrapping-rke2-with-argocd-prometheus-and-cert-manager">How to Guide: Boostrapping RKE2 with ArgoCD, Prometheus, and Cert-Manager</a>
    <ul>
      <li><a href="#introduction">Introduction</a></li>
      <li><a href="#table-of-contents">Table of Contents</a></li>
      <li><a href="#prerequisites">Prerequisites</a></li>
      <li><a href="#steps">Steps</a>
        <ul>
          <li><a href="#1-create-a-new-namespace-for-argocd">1. Create a new namespace for ArgoCD</a></li>
          <li><a href="#2-argocd">2. ArgoCD</a>
            <ul>
              <li><a href="#argo-components">Argo Components</a></li>
            </ul>
          </li>
          <li><a href="#21-install-helm">2.1 Install Helm</a></li>
          <li><a href="#3-login-to-argocd">3. Login to ArgoCD</a></li>
          <li><a href="#4-update-password">4. Update Password</a></li>
          <li><a href="#5-add-repositories">5. Add Repositories</a></li>
          <li><a href="#6-create-a-new-project">6. Create a new project</a></li>
          <li><a href="#7-install-prometheus">7. Install Prometheus</a>
            <ul>
              <li><a href="#using-argocd">Using ArgoCD</a></li>
            </ul>
          </li>
          <li><a href="#cert-manager">Cert-Manager</a>
            <ul>
              <li><a href="#cm-components">CM Components</a></li>
              <li><a href="#install-cert-manager">Install Cert-Manager</a></li>
              <li><a href="#cluster-issuer">Cluster Issuer</a></li>
            </ul>
          </li>
          <li><a href="#ingress-controller">Ingress Controller</a></li>
        </ul>
      </li>
    </ul>
  </li>
</ul>

<h2 id="prerequisites">Prerequisites</h2>

<ul>
  <li>RKE2 Cluster</li>
  <li>kubectl</li>
  <li>ssh access to RKE2 cluster</li>
</ul>

<h2 id="steps">Steps</h2>

<h3 id="1-create-a-new-namespace-for-argocd">1. Create a new namespace for ArgoCD</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># first switch to proper context</span>
<span class="s">kubectl config use-context &lt;cluster-name&gt;</span>
<span class="s">kubectl create namespace argocd</span>
</code></pre></div></div>

<h3 id="2-argocd">2. ArgoCD</h3>

<p>Argo CD is a declarative, GitOps continuous delivery tool for Kubernetes applications. In the context of Kubernetes, GitOps is a set of practices that use Git as the source of truth for declarative infrastructure and applications. With Argo CD, you can manage and automate the deployment of your Kubernetes applications using Git repositories as the source of configuration and versioning.</p>

<h4 id="argo-components">Argo Components</h4>

<p>Here are some key aspects of Argo CD in relation to Kubernetes:</p>

<ul>
  <li><strong>Declarative Configuration</strong>: Argo CD uses declarative YAML files to describe the desired state of your Kubernetes applications. These files are typically stored in a Git repository.</li>
  <li><strong>Continuous Delivery (CD)</strong>: Argo CD automates the deployment of applications to Kubernetes clusters. It continuously monitors the Git repository for changes and ensures that the actual cluster state matches the desired state defined in the Git repository.</li>
  <li><strong>GitOps Workflow</strong>: Argo CD follows the GitOps workflow, where the Git repository serves as the single source of truth for both the application configuration and the deployment state. Changes to the Git repository trigger automatic updates to the Kubernetes cluster.</li>
  <li><strong>Application Synchronization</strong>: Argo CD maintains the desired state of applications in the Git repository by automatically synchronizing with the current state of the Kubernetes cluster. It detects any discrepancies and reconciles them to ensure that the cluster state matches the configuration in Git.</li>
  <li><strong>Multi-Cluster Support</strong>: Argo CD supports managing applications across multiple Kubernetes clusters. This is particularly useful in a multi-environment or multi-region setup.</li>
  <li><strong>Web UI and CLI</strong>: Argo CD provides a web-based user interface (UI) and a command-line interface (CLI) for managing and monitoring applications.</li>
  <li><strong>Rollback and Roll Forward</strong>: Argo CD allows you to roll back or roll forward to a specific version of your application by changing the desired state in the Git repository.</li>
</ul>

<p>Using Argo CD simplifies and streamlines the deployment and management of Kubernetes applications, making it easier to maintain consistency and traceability across different environments.</p>

<h3 id="21-install-helm">2.1 Install Helm</h3>

<p>I prefer to use a separate VM/controller to perform all Helm installations. This is not required, but it is recommended. <strong>Note</strong> this does not need to be performed on the RKE2 server.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Use curl to download release and untar</span>
<span class="s">curl -L https://get.helm.sh/helm-v3.13.2-linux-amd64.tar.gz | tar xz</span>
<span class="s">cd linux-amd64</span>
<span class="s">chmod +x helm</span>
<span class="s">sudo mv helm /usr/local/bin/helm</span>
<span class="s">cd ../</span>
<span class="s">rm -rf linux-amd64</span>
</code></pre></div></div>

<p>Add Argo repo to helm</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm repo add argo https://argoproj.github.io/argo-helm</span>
<span class="s">helm repo update</span>
</code></pre></div></div>

<p>For this step we are going to use the <code class="language-plaintext highlighter-rouge">HelmChart</code> CRD to install ArgoCD. This will allow us to use the <code class="language-plaintext highlighter-rouge">HelmRelease</code> CRD to manage the ArgoCD application. You need to add the following file to <code class="language-plaintext highlighter-rouge">/var/lib/rancher/rke2/server/manifests/</code> on the RKE2 server. This will install the <code class="language-plaintext highlighter-rouge">HelmRelease</code> CRD and the ArgoCD application.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cat &lt;&lt;EOF &gt; argocd-values.yaml</span>
<span class="na">controller</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s">30s</span>
<span class="na">server</span><span class="pi">:</span>
  <span class="na">service</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">ClusterIP</span>
  <span class="na">extensions</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s">30s</span>
<span class="na">repoServer</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s">30s</span>
<span class="na">applicationSet</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s">30s</span>
<span class="na">notifications</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s">30s</span>
<span class="na">redis</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s">30s</span>
<span class="na">rbac</span><span class="pi">:</span>
  <span class="na">defaultPolicy</span><span class="pi">:</span> <span class="s1">'</span><span class="s">role:readonly'</span>
<span class="na">dex</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">false</span>
<span class="s">EOF</span>
</code></pre></div></div>

<p>Now install the chart:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm install argocd \</span>
  <span class="s">-n argocd \</span>
  <span class="s">--create-namespace \</span>
  <span class="s">-f argocd-values.yaml argo/argo-cd</span>
</code></pre></div></div>

<p>Now wait for all pods to be running:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl -n argocd get pods -w</span>
</code></pre></div></div>

<h3 id="3-login-to-argocd">3. Login to ArgoCD</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">password=$(kubectl -n argocd get secret argocd-initial-admin-secret -o jsonpath="{.data.password}" | base64 -d)</span>
<span class="c1"># port forward to argocd server</span>
<span class="s">kubectl -n argocd port-forward svc/argocd-server 8080:80</span>
<span class="s">argocd login localhost:8080 --username admin --password $password --insecure</span>
</code></pre></div></div>

<h3 id="4-update-password">4. Update Password</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">argocd account update-password --account admin --current-password $password --new-password &lt;new-password&gt;</span>
<span class="c1"># delete initial secret</span>
<span class="s">kubectl -n argocd delete secret argocd-initial-admin-secret</span>
</code></pre></div></div>

<h3 id="5-add-repositories">5. Add Repositories</h3>

<p><em>Note</em> steps 5 and 6 have been added to the <a href="scripts/argo.setup.sh">argocd-setup.sh</a> script.</p>

<p>Let us add the prometheus, jetstack and bitnami repositories to ArgoCD. This will allow us to install applications from these repositories.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">argocd repo add https://charts.bitnami.com/bitnami --type helm --name bitnami</span>
<span class="s">argocd repo add https://charts.jetstack.io --type helm --name jetstack</span>
<span class="s">argocd repo add https://kubernetes-charts.storage.googleapis.com --type helm --name stable</span>
<span class="s">argocd repo add https://prometheus-community.github.io/helm-chart --type helm --name prometheus-community</span>
</code></pre></div></div>

<h3 id="6-create-a-new-project">6. Create a new project</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">argocd proj create monitoring</span>
</code></pre></div></div>

<h3 id="7-install-prometheus">7. Install Prometheus</h3>

<p>I have experienced issues with installing the kube-prometheus-stack chart using ArgoCD. I suspect that the issue is related to the Prometheus CRDs, therefore, I have decided to install the chart using the <code class="language-plaintext highlighter-rouge">Helm</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm repo add prometheus-community https://prometheus-community.github.io/helm-chart</span>
<span class="s">helm repo update</span>
<span class="s">helm install --namespace monitoring-system --create-namespace monitoring prometheus-community/kube-prometheus-stack</span>
</code></pre></div></div>

<h4 id="using-argocd">Using ArgoCD</h4>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">argocd app create monitoring --repo https://prometheus-community.github.io/helm-chart \</span>
   <span class="s">--helm-chart kube-prometheus-stack \</span>
   <span class="s">--revision 54.2.0 \</span>
   <span class="s">--dest-namespace monitoring-system \</span>
   <span class="s">--dest-server https://kubernetes.default.svc \</span>
   <span class="s">--project monitoring</span>
</code></pre></div></div>

<h3 id="cert-manager">Cert-Manager</h3>

<p>Cert-manager is a Kubernetes native certificate management controller. Its primary purpose is to automate the management and issuance of TLS certificates within Kubernetes clusters. TLS (Transport Layer Security) certificates are used to secure communication over the web, and they are commonly used to enable HTTPS for web applications.</p>

<h4 id="cm-components">CM Components</h4>

<p>Here are key aspects of cert-manager in relation to Kubernetes:</p>

<ul>
  <li><strong>Certificate Issuance and Renewal</strong>: Cert-manager automates the process of obtaining and renewing TLS certificates from various certificate authorities (CAs) such as Let’s Encrypt. It allows you to define certificate issuers and certificate requests as Kubernetes resources.</li>
  <li><strong>Integration with ACME Protocols</strong>: Cert-manager supports the ACME (Automatic Certificate Management Environment) protocol, which is commonly used by Let’s Encrypt. This enables automatic certificate provisioning and renewal.</li>
  <li><strong>Custom Resource Definitions (CRDs)</strong>: Cert-manager extends Kubernetes by introducing custom resource definitions (CRDs) for defining certificate issuers, certificate requests, and certificates. This allows you to manage certificates as part of your Kubernetes configuration.</li>
  <li><strong>Webhook and Controller Architecture</strong>: Cert-manager uses a webhook and controller architecture to interact with Kubernetes resources and respond to changes. The controller monitors the state of certificate-related resources and takes actions to ensure the requested certificates are obtained and renewed as needed.</li>
  <li><strong>Integration with Ingress Controllers</strong>: Cert-manager integrates with Kubernetes Ingress controllers, making it easy to secure web applications by automatically provisioning TLS certificates for Ingress resources.</li>
  <li><strong>Support for Multiple Issuers</strong>: Cert-manager supports multiple issuers, allowing you to choose different certificate authorities or even self-signed certificates based on the specific requirements of your applications.</li>
  <li><strong>Web UI and CLI</strong>: Cert-manager provides a web-based user interface (UI) and a command-line interface (CLI) for managing and monitoring certificates.</li>
</ul>

<p>By using cert-manager, Kubernetes users can ensure that their applications are using valid and up-to-date TLS certificates without manual intervention. This is crucial for maintaining the security and integrity of communication within a Kubernetes cluster and between external clients and services.</p>

<h4 id="install-cert-manager">Install Cert-Manager</h4>

<p>We will use ArgoCD to manage the installation of cert-manager. You can either use the web UI or the CLI to install the application. I will use the CLI.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">echo "Adding cert-manager repo"</span>
<span class="s">argocd repo add https://charts.jetstack.io --type helm --name jetstack</span>
<span class="s">echo "Creating cert-manager namespace"</span>
<span class="s">kubectl create ns cert-manager</span>
<span class="s">echo "Creating cert-manager application"</span>
<span class="s">argocd app create cert-manager --repo https://charts.jetstack.io \</span>
   <span class="s">--helm-chart cert-manager \</span>
   <span class="s">--revision v1.5.3 \</span>
   <span class="s">--dest-namespace cert-manager \</span>
   <span class="s">--dest-server https://kubernetes.default.svc \</span>
   <span class="s">--project cert-manager</span>
</code></pre></div></div>

<h4 id="cluster-issuer">Cluster Issuer</h4>

<p>In the context of cert-manager and Kubernetes, a <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> is a custom resource definition (CRD) used to define a certificate issuer at the cluster level. It is a way to configure and manage certificate authorities (CAs) for obtaining TLS certificates across the entire Kubernetes cluster.</p>

<p>Here are key points about ClusterIssuer:</p>

<ul>
  <li><strong>Scope</strong>: Unlike a regular Issuer, which is specific to a namespace, a ClusterIssuer is designed to have a global scope across the entire Kubernetes cluster. This means that certificates issued by a ClusterIssuer can be used by resources in any namespace.</li>
  <li><strong>Centralized Configuration</strong>: ClusterIssuer allows you to define a centralized configuration for a certificate authority, such as the endpoint of the CA server, authentication credentials, and other settings needed to interact with the CA.</li>
  <li><strong>Multiple Issuers</strong>: You can have multiple ClusterIssuer resources in a cluster, each configured to interact with a different certificate authority or configuration. This flexibility allows you to use different CAs for different purposes or to meet specific security requirements.</li>
  <li><strong>Used with Cert-manager</strong>: ClusterIssuer is part of the cert-manager project and works in conjunction with the cert-manager controller. Cert-manager uses the information specified in a ClusterIssuer resource to manage the lifecycle of TLS certificates issued by the associated CA.</li>
</ul>

<p>For ease of use, we are going to use letsencrypt as our certificate authority. We will use the <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> resource to configure cert-manager to use the Let’s Encrypt staging and production environments.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">cert-manager.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">ClusterIssuer</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">letsencrypt-prod</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">acme</span><span class="pi">:</span>
    <span class="na">server</span><span class="pi">:</span> <span class="s">https://acme-v02.api.letsencrypt.org/directory</span>
    <span class="na">email</span><span class="pi">:</span> <span class="s">your-email@example.com</span>
    <span class="na">privateKeySecretRef</span><span class="pi">:</span>
      <span class="na">name</span><span class="pi">:</span> <span class="s">letsencrypt-prod</span>
    <span class="na">solvers</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">http01</span><span class="pi">:</span>
        <span class="na">ingress</span><span class="pi">:</span>
          <span class="na">class</span><span class="pi">:</span> <span class="s">nginx</span>
</code></pre></div></div>

<p>In this example, the <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> is named “letsencrypt-prod,” and it is configured to use the Let’s Encrypt ACME server to issue certificates. The configuration includes the email address for notifications and specifies the <code class="language-plaintext highlighter-rouge">http01</code> challenge for domain validation.</p>

<p>This <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> can then be referenced in <code class="language-plaintext highlighter-rouge">Certificate</code> resources (another cert-manager CRD) across different namespaces within the cluster. Cert-manager will use the <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> configuration to automatically manage the lifecycle of TLS certificates associated with those Certificate resources.</p>

<h3 id="ingress-controller">Ingress Controller</h3>

<p>An Ingress controller is an application that monitors Ingress resources via the Kubernetes API and updates the configuration of a load balancer in case of any changes. It also handles dynamic configuration changes, such as adding or removing routes, without requiring any manual intervention. We have already configured the NGINX Ingress Controller in the previous section. We will use it to expose our applications to the outside world and will use the <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> we created in the previous section to issue TLS certificates for our applications. There are a lot of annotations that you can add to your <code class="language-plaintext highlighter-rouge">Ingress</code> resource to configure how the NGINX Ingress Controller handles individual routes. You can find the full list of annotations <a href="https://kubernetes.github.io/ingress-nginx/user-guide/nginx-configuration/annotations/">here</a>.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">networking.k8s.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Ingress</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">ingress</span>
  <span class="na">annotations</span><span class="pi">:</span>
    <span class="na">kubernetes.io/ingress.class</span><span class="pi">:</span> <span class="s">nginx</span>
    <span class="na">cert-manager.io/cluster-issuer</span><span class="pi">:</span> <span class="s">letsencrypt-prod</span>
    <span class="na">nginx.ingress.kubernetes.io/ssl-redirect</span><span class="pi">:</span> <span class="s2">"</span><span class="s">true"</span>
    <span class="na">nginx.ingress.kubernetes.io/force-ssl-redirect</span><span class="pi">:</span> <span class="s2">"</span><span class="s">true"</span>
    <span class="na">nginx.ingress.kubernetes.io/rewrite-target</span><span class="pi">:</span> <span class="s">/$2</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">rules</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">host</span><span class="pi">:</span> <span class="s">hello-world.info</span>
      <span class="na">http</span><span class="pi">:</span>
        <span class="na">paths</span><span class="pi">:</span>
          <span class="pi">-</span> <span class="na">path</span><span class="pi">:</span> <span class="s">/</span>
            <span class="na">pathType</span><span class="pi">:</span> <span class="s">Prefix</span>
            <span class="na">backend</span><span class="pi">:</span>
              <span class="na">service</span><span class="pi">:</span>
                <span class="na">name</span><span class="pi">:</span> <span class="s">web</span>
                <span class="na">port</span><span class="pi">:</span>
                  <span class="na">number</span><span class="pi">:</span> <span class="m">8080</span>
  <span class="na">tls</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">hosts</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">https-example.foo.com</span>
    <span class="na">secretName</span><span class="pi">:</span> <span class="s">helloworld-tls</span>
</code></pre></div></div>

<p>In this example, we have configured the NGINX Ingress Controller to use the <code class="language-plaintext highlighter-rouge">letsencrypt-prod</code> <code class="language-plaintext highlighter-rouge">ClusterIssuer</code> to issue TLS certificates for the <code class="language-plaintext highlighter-rouge">hello-world.info</code> domain. The <code class="language-plaintext highlighter-rouge">Ingress</code> resource also specifies that all requests to the <code class="language-plaintext highlighter-rouge">hello-world.info</code> domain should be redirected to HTTPS. <em>Note</em> that by adding the <code class="language-plaintext highlighter-rouge">cert-manager</code> annotation to the <code class="language-plaintext highlighter-rouge">Ingress</code> resource, we are telling cert-manager to ask lets-encrypt to issue a TLS certificate for this domain, and it will be stored in the <code class="language-plaintext highlighter-rouge">helloworld-tls</code> secret.</p>

<p>Stay tuned for the next part of this series where we will configure <code class="language-plaintext highlighter-rouge">Longhorn</code> to provide persistent storage for our applications.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="argocd" /><category term="devops" /><category term="cluster" /><category term="prometheus" /><category term="cert-manager" /><summary type="html"><![CDATA[Howto guide for ensuring RKE2 is bootstrapped with ArgoCD, Prometheus, and Cert-Manager]]></summary></entry><entry><title type="html">Cilium Metrics</title><link href="https://mitchmurphy.io/cilium-prom/" rel="alternate" type="text/html" title="Cilium Metrics" /><published>2022-12-02T00:00:00-05:00</published><updated>2022-12-02T00:00:00-05:00</updated><id>https://mitchmurphy.io/cilium-prom</id><content type="html" xml:base="https://mitchmurphy.io/cilium-prom/"><![CDATA[<h1 id="update-cilium-to-expose-prometheus-metrics">Update Cilium to expose Prometheus metrics</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Expose Cilium Metrics to Prometheus</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2023-12-15</span>
</code></pre></div></div>

<hr />

<ul>
  <li><a href="#update-cilium-to-expose-prometheus-metrics">Update Cilium to expose Prometheus metrics</a></li>
  <li><a href="#introduction">Introduction</a>
    <ul>
      <li><a href="#prerequisites">Prerequisites</a></li>
      <li><a href="#prometheus">Prometheus</a>
        <ul>
          <li><a href="#prometheus-overview">Prometheus Overview</a></li>
          <li><a href="#prometheus-installation">Prometheus Installation</a></li>
        </ul>
      </li>
      <li><a href="#cilium">Cilium</a>
        <ul>
          <li><a href="#cilium-and-prometheus">Cilium and Prometheus</a></li>
          <li><a href="#cilium-upgrade">Cilium Upgrade</a></li>
          <li><a href="#cilium-servicemonitor-verification">Cilium ServiceMonitor Verification</a></li>
          <li><a href="#cilium-grafana-dashboards">Cilium Grafana Dashboards</a></li>
        </ul>
      </li>
    </ul>
  </li>
</ul>

<h1 id="introduction">Introduction</h1>

<p>This guide serves as a follow up to a previous article covering how to configure RKE2 to use Cilium as the CNI (and fully replace kube-proxy)</p>

<h2 id="prerequisites">Prerequisites</h2>

<ul>
  <li>RKE2 Cluster</li>
  <li>cilium</li>
  <li>kubectl</li>
  <li>helm</li>
</ul>

<h2 id="prometheus">Prometheus</h2>

<p>Prometheus is an open-source monitoring and alerting toolkit designed for reliability and scalability. It is particularly well-suited for monitoring dynamic, cloud-native environments such as Kubernetes. Here’s an overview of Prometheus and how it facilitates monitoring in a Kubernetes environment:</p>

<h3 id="prometheus-overview">Prometheus Overview</h3>

<ol>
  <li><strong>Data Model</strong>:
    <ul>
      <li>Prometheus follows a multi-dimensional data model, where time-series data is identified by metric names and key-value pairs called labels.
Metrics represent numerical values that can be observed and monitored over time.</li>
    </ul>
  </li>
  <li><strong>Data Retrieval</strong>:
    <ul>
      <li>Prometheus uses a pull-based approach to collect metrics from monitored targets.
Each target (e.g., a Kubernetes node or container) exposes an HTTP endpoint where Prometheus can fetch metrics.</li>
    </ul>
  </li>
  <li><strong>Scalability</strong>:
    <ul>
      <li>Prometheus is designed to be highly scalable, making it suitable for large-scale distributed systems like Kubernetes.
It can handle a high volume of metrics from numerous targets.</li>
    </ul>
  </li>
  <li><strong>Query Language</strong>:
    <ul>
      <li>Prometheus Query Language (PromQL) allows users to express complex queries to analyze and aggregate collected metrics.
PromQL facilitates the creation of custom dashboards and alerts.
Monitoring Kubernetes with Prometheus:</li>
    </ul>
  </li>
  <li><strong>Exporter Components</strong>:
    <ul>
      <li>Kubernetes exposes a rich set of metrics through its API server, kubelet, and other components.
Prometheus exporters are used to convert these metrics into a format that Prometheus can scrape.</li>
    </ul>
  </li>
  <li><strong>Service Discovery</strong>:
    <ul>
      <li>Prometheus uses service discovery mechanisms to automatically discover and monitor new instances of services as they are deployed in Kubernetes.
Kubernetes Service Discovery and DNS-based service discovery are commonly used.</li>
    </ul>
  </li>
  <li><strong>Instrumentation</strong>:
    <ul>
      <li>Kubernetes components are instrumented to expose metrics in a format that Prometheus understands.
Prometheus also supports custom instrumentation, allowing users to expose application-specific metrics.</li>
    </ul>
  </li>
  <li><strong>Alerting and Monitoring</strong>:
    <ul>
      <li>Prometheus provides a built-in alerting system that allows users to define alerting rules based on metric conditions.
Grafana is often used in conjunction with Prometheus to create dashboards for visualizing metrics.</li>
    </ul>
  </li>
  <li><strong>Integration with Kubernetes Ecosystem</strong>:
    <ul>
      <li>Prometheus is a CNCF (Cloud Native Computing Foundation) project and is well-integrated with the Kubernetes ecosystem.
It works seamlessly with other tools like Grafana, Alertmanager, and Kubernetes itself.</li>
    </ul>
  </li>
</ol>

<p>In summary, Prometheus is a powerful monitoring solution for Kubernetes, offering a flexible and scalable approach to collecting, querying, and alerting based on the metrics generated by the Kubernetes ecosystem. It plays a crucial role in ensuring the reliability and performance of applications deployed in Kubernetes clusters.</p>

<h3 id="prometheus-installation">Prometheus Installation</h3>

<p>The Prometheus stack includes a few components that greatly help SREs/administrators monitor/observe deployed Kubernetes resources. These include:</p>

<ul>
  <li>The <a href="https://github.com/prometheus-operator/prometheus-operator">Prometheus Operator</a></li>
  <li>Highly available <a href="https://prometheus.io/">Prometheus</a></li>
  <li>Highly available <a href="https://github.com/prometheus/alertmanager">Alertmanager</a></li>
  <li><a href="https://github.com/prometheus/node_exporter">Prometheus node-exporter</a></li>
  <li><a href="https://github.com/kubernetes-sigs/prometheus-adapter">Prometheus Adapter for Kubernetes Metrics APIs</a></li>
  <li><a href="https://github.com/kubernetes/kube-state-metrics">kube-state-metrics</a></li>
  <li><a href="https://grafana.com/">Grafana</a></li>
</ul>

<p>Installing the Prometheus stack on Kubernetes using Helm is a common and convenient approach. Helm is a package manager for Kubernetes that simplifies the deployment and management of applications. Here’s a step-by-step guide for Kubernetes administrators on installing the Prometheus stack using Helm:</p>

<ol>
  <li>
    <p>Add Prometheus Helm Repository:</p>

    <ul>
      <li>Add the Prometheus Helm repository to your Helm client.</li>
    </ul>
  </li>
</ol>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm repo add prometheus-community https://prometheus-community.github.io/helm-charts</span>
<span class="s">helm repo update</span>
</code></pre></div></div>

<ol>
  <li>
    <p>Create Namespace (Optional):</p>

    <ul>
      <li>Create a dedicated namespace for Prometheus if desired.</li>
    </ul>
  </li>
</ol>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl create namespace monitoring</span>
</code></pre></div></div>

<ol>
  <li>
    <p>Install Prometheus Operator:</p>

    <ul>
      <li>Install the Prometheus Operator using Helm.</li>
    </ul>
  </li>
</ol>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm install prometheus prometheus-community/kube-prometheus-stack -n monitoring --create-namespace</span>
</code></pre></div></div>

<ol>
  <li>
    <p>Verify Installation:</p>

    <ul>
      <li>Check the status of the deployed resources.</li>
    </ul>
  </li>
</ol>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl get pods -n monitoring</span>
</code></pre></div></div>

<ol>
  <li>
    <p>Access Prometheus Dashboard:</p>

    <ul>
      <li>Prometheus comes with a web-based dashboard. Expose it for access.</li>
    </ul>
  </li>
</ol>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl port-forward -n monitoring svc/prometheus-stack-kube-prom-prometheus </span><span class="m">9090</span>
</code></pre></div></div>

<blockquote>
  <p>Access the Prometheus dashboard at <a href="http://localhost:9090">http://localhost:9090</a> in your web browser.</p>
</blockquote>

<ol>
  <li>
    <p>Access Grafana Dashboard (Optional):</p>

    <ul>
      <li>Grafana is included in the Prometheus stack. Expose it for access.</li>
    </ul>
  </li>
</ol>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl port-forward -n monitoring svc/prometheus-stack-grafana 3000:80</span>
</code></pre></div></div>

<blockquote>
  <p>Access the Grafana dashboard at <a href="http://localhost:3000">http://localhost:3000</a> and log in (default credentials are admin/prom-operator).</p>
</blockquote>

<ol>
  <li>
    <p>Configure Data Source in Grafana (Optional):</p>

    <ul>
      <li>Configure Prometheus as a data source in Grafana.
        <ul>
          <li>URL: http://prometheus-stack-kube-prom-prometheus:9090</li>
          <li>Save the configuration.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li>
    <p>Explore and Customize:</p>

    <ul>
      <li>Explore the Prometheus dashboard and Grafana to monitor your Kubernetes cluster.</li>
      <li>Customize Grafana dashboards and Prometheus alerting rules as needed.</li>
    </ul>
  </li>
</ol>

<p>By following these steps, Kubernetes administrators can easily set up and start using the Prometheus stack for monitoring their Kubernetes clusters. The Helm charts provided by the Prometheus community simplify the installation process and allow for customization based on specific monitoring requirements. Take note of the namespace where you install the prometheus-stack to as we will need to specify that when we upgrade Cilium. Stay tuned when I cover configuring alerts in Prometheus and integration with Alertmanager!</p>

<h2 id="cilium">Cilium</h2>

<p>Please refer to my previous post to find more information on what Cilium offers.</p>

<h3 id="cilium-and-prometheus">Cilium and Prometheus</h3>

<p>Integrating Cilium and Prometheus in a Kubernetes environment brings several benefits, particularly in terms of exposing advanced metrics and enhancing the observability of your microservices-based architecture. Here are the key advantages of integrating Cilium and Prometheus:</p>

<ol>
  <li><strong>Rich Network Visibility</strong>:
    <ul>
      <li><strong>Cilium Network Security</strong>:
        <ul>
          <li>Cilium provides advanced network security features, including API-aware network security policies, load balancing, and encryption.</li>
          <li>Prometheus integration with Cilium allows you to capture and visualize metrics related to network security, such as the number of allowed/denied connections and data on network policies.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Fine-Grained Service Metrics</strong>:
    <ul>
      <li><strong>Service-Aware Metrics</strong>:
        <ul>
          <li>Cilium can enforce policies at the service or application layer, providing insights into the interactions between microservices.</li>
          <li>Prometheus can scrape and expose fine-grained metrics related to service communication, allowing you to monitor service-level performance and troubleshoot issues.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Distributed Tracing</strong>:
    <ul>
      <li><strong>Tracepoint Metrics</strong>:
        <ul>
          <li>Cilium includes tracepoint-based metrics that can be exposed through Prometheus.</li>
          <li>By integrating Cilium and Prometheus, you can leverage these metrics for distributed tracing, gaining visibility into the flow of requests across microservices and identifying bottlenecks or latency issues.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Security Metrics</strong>:
    <ul>
      <li><strong>Security Incident Monitoring</strong>:
        <ul>
          <li>Cilium enhances security by providing metrics related to security incidents and policy enforcement.</li>
          <li>Prometheus integration enables monitoring of security-related metrics, helping Kubernetes engineers detect and respond to security events in real-time.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Efficient Resource Utilization</strong>:
    <ul>
      <li><strong>Resource Consumption Metrics</strong>:
        <ul>
          <li>Prometheus can collect and expose metrics related to resource consumption at the network level.</li>
          <li>This integration allows Kubernetes engineers to optimize resource allocation, identify performance bottlenecks, and ensure efficient use of network resources.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Customizable Dashboards</strong>:
    <ul>
      <li><strong>Grafana Integration</strong>:
        <ul>
          <li>Prometheus integrates seamlessly with Grafana, a popular visualization tool.</li>
          <li>Engineers can create customizable dashboards in Grafana to visualize Cilium and Kubernetes metrics, providing a comprehensive view of the entire system’s health and performance.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Scalability and Performance Monitoring</strong>:
    <ul>
      <li><strong>Scalability Metrics</strong>:
        <ul>
          <li>Cilium and Prometheus integration enables monitoring of metrics related to the scalability and performance of microservices.</li>
          <li>Engineers can use this information to optimize configurations, scale resources based on demand, and ensure a responsive and scalable application architecture.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li><strong>Alerting and Automation</strong>:
    <ul>
      <li><strong>Alertmanager Integration</strong>:
        <ul>
          <li>Prometheus integrates with Alertmanager to provide alerting capabilities based on predefined rules.</li>
          <li>Engineers can set up alerts for key metrics, enabling proactive monitoring and automated responses to potential issues.</li>
        </ul>
      </li>
    </ul>
  </li>
</ol>

<p>In summary, integrating Cilium and Prometheus in a Kubernetes environment enhances observability by providing detailed metrics related to network security, service communication, distributed tracing, and resource utilization. This integration empowers Kubernetes engineers to monitor, analyze, and optimize the performance, security, and scalability of their microservices applications.</p>

<h3 id="cilium-upgrade">Cilium Upgrade</h3>

<p>In order to integrate our previously installed Cilium/Hubble we need to update a few of our Helm values, particularly that involving ServiceMonitors. Update the file containing the values (detailed <a href="https://mitchmurphy.io/cilium-rke2/#install-cilium">here</a>) to:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">cluster</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">smig-cluster1</span>
  <span class="na">id</span><span class="pi">:</span> <span class="m">11</span>
<span class="na">prometheus</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">serviceMonitor</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">false</span>
<span class="na">dashboards</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
<span class="na">hubble</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">dns:query;ignoreAAAA</span>
    <span class="pi">-</span> <span class="s">drop</span>
    <span class="pi">-</span> <span class="s">tcp</span>
    <span class="pi">-</span> <span class="s">flow</span>
    <span class="pi">-</span> <span class="s">icmp</span>
    <span class="pi">-</span> <span class="s">http</span>
    <span class="na">dashboards</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring</span>
      <span class="na">labels</span><span class="pi">:</span>
        <span class="na">release</span><span class="pi">:</span> <span class="s">prometheus-stack</span>
  <span class="na">relay</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">prometheus</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">serviceMonitor</span><span class="pi">:</span>
        <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
        <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring</span>
        <span class="na">labels</span><span class="pi">:</span>
          <span class="na">release</span><span class="pi">:</span> <span class="s">prometheus-stack</span>
  <span class="na">ui</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">baseUrl</span><span class="pi">:</span> <span class="s2">"</span><span class="s">/"</span>
<span class="na">version</span><span class="pi">:</span> <span class="s">1.14.3</span>
<span class="na">operator</span><span class="pi">:</span>
  <span class="na">prometheus</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring</span>
      <span class="na">labels</span><span class="pi">:</span>
        <span class="na">release</span><span class="pi">:</span> <span class="s">prometheus-stack</span>
  <span class="na">dashboards</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
<span class="na">envoy</span><span class="pi">:</span>
  <span class="na">prometheus</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring</span>
      <span class="na">labels</span><span class="pi">:</span>
        <span class="na">release</span><span class="pi">:</span> <span class="s">prometheus-stack</span>
<span class="na">clustermesh</span><span class="pi">:</span>
  <span class="na">apiserver</span><span class="pi">:</span>
    <span class="na">metrics</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">false</span>
      <span class="na">serviceMonitor</span><span class="pi">:</span>
        <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
        <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring</span>
        <span class="na">labels</span><span class="pi">:</span>
          <span class="na">release</span><span class="pi">:</span> <span class="s">prometheus-stack</span>
</code></pre></div></div>

<p>Take note of the label that is added to each ServiceMonitor, this must be present in order for Prometheus to detect the “target” and start scraping it. Now let’s upgrade Cilium:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cilium upgrade -f cilium.yaml</span>
</code></pre></div></div>

<h3 id="cilium-servicemonitor-verification">Cilium ServiceMonitor Verification</h3>

<p>n order to verify that Prometheus is picking up these new targets, you need to port-forward and make sure that they show up under Status -&gt; Targets.</p>

<h3 id="cilium-grafana-dashboards">Cilium Grafana Dashboards</h3>

<p>Because we specified in our values file that we wish to create Grafana dashboards, these get created as ConfigMaps and automatically picked up by Grafana. Until we expose Grafana as an Ingress, we must port-forward to it:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl port-forward svc/prometheus-stack-grafana 8080:80 &amp;</span>
</code></pre></div></div>

<p>Now visit our <a href="http://localhost:8080/dashboards">dashboards</a>, and click on the Hubble dashboard. Because we have not deployed anything to our cluster we should not see much here, but as you can see Cilium/Hubble provides quite advanced metrics! We will visit this dashboard again after we deploy a few things and test our system!</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="cilium" /><category term="devops" /><category term="cluster" /><category term="prometheus" /><category term="servicemonitor" /><summary type="html"><![CDATA[Update Cilium to expose Prometheus metrics]]></summary></entry><entry><title type="html">RKE2 Install with Cilium, Hubble and Cluster Mesh</title><link href="https://mitchmurphy.io/cilium-rke2/" rel="alternate" type="text/html" title="RKE2 Install with Cilium, Hubble and Cluster Mesh" /><published>2022-11-25T00:00:00-05:00</published><updated>2022-11-25T00:00:00-05:00</updated><id>https://mitchmurphy.io/cilium-rke2</id><content type="html" xml:base="https://mitchmurphy.io/cilium-rke2/"><![CDATA[<h1 id="how-to-guide-rke2-install-with-cilium-hubble-and-cluster-mesh">How to Guide: RKE2 Install with Cilium, Hubble and Cluster Mesh</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">RKE2 Install with Cilium, Hubble and Cluster Mesh</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2023-11-25</span>
</code></pre></div></div>

<hr />

<h2 id="table-of-contents">Table of contents</h2>
<ul>
  <li><a href="#how-to-guide-rke2-install-with-cilium-hubble-and-cluster-mesh">How to Guide: RKE2 Install with Cilium, Hubble and Cluster Mesh</a>
    <ul>
      <li><a href="#table-of-contents">Table of contents</a></li>
      <li><a href="#introduction">Introduction</a>
        <ul>
          <li><a href="#what-is-cilium">What is Cilium?</a></li>
          <li><a href="#what-is-hubble">What is Hubble?</a></li>
        </ul>
      </li>
      <li><a href="#prerequisites">Prerequisites</a>
        <ul>
          <li><a href="#networking-pre-requisites">Networking Pre-Requisites</a></li>
          <li><a href="#kernel-configuration">Kernel Configuration</a></li>
          <li><a href="#selinux-configuration">selinux Configuration</a></li>
          <li><a href="#firewall-configuration">Firewall Configuration</a></li>
          <li><a href="#storage-configuration">Storage Configuration</a></li>
        </ul>
      </li>
      <li><a href="#rke2-installation">RKE2 Installation</a>
        <ul>
          <li><a href="#control-plane-node">Control Plane Node</a>
            <ul>
              <li><a href="#download-and-install-rke2">Download and Install RKE2</a></li>
              <li><a href="#start-rke2">Start RKE2</a></li>
              <li><a href="#installation-cilium-cli">Installation Cilium CLI</a></li>
              <li><a href="#verify-rke2">Verify RKE2</a></li>
            </ul>
          </li>
        </ul>
      </li>
      <li><a href="#install-cilium">Install Cilium</a>
        <ul>
          <li><a href="#verify-cilium">Verify Cilium</a></li>
        </ul>
      </li>
      <li><a href="#worker-nodes">Worker Nodes</a>
        <ul>
          <li><a href="#verify-rke2-agent">Verify RKE2 Agent</a></li>
        </ul>
      </li>
      <li><a href="#metallb">MetalLB</a>
        <ul>
          <li><a href="#what-is-metallb">What is MetalLB?</a></li>
          <li><a href="#intall-metallb">Intall MetalLB</a></li>
          <li><a href="#verify-metallb">Verify MetalLB</a></li>
        </ul>
      </li>
      <li><a href="#cilium-cluster-mesh">Cilium Cluster Mesh</a></li>
      <li><a href="#create-servicemonitors">Create ServiceMonitors</a></li>
      <li><a href="#verify-cilium-servicemonitor">Verify Cilium ServiceMonitor</a></li>
    </ul>
  </li>
</ul>

<div id="introduction" />

<h2 id="introduction">Introduction</h2>

<p>This guide will walk you through the steps to install RKE2, Cilium, Hubble, Cluster Mesh, MetalLB, Nginx-Ingress, Cert Manager, the PLG stack, Fluent Bit, Harbor and Longhorn on a Windows Server/Data Center 2022 using Hyper-V VMs running Rocky Linux 8.8.</p>

<div id="what-is-cilium" />

<h3 id="what-is-cilium">What is Cilium?</h3>

<p>Cilium is an open-source software project that provides networking and security for containerized applications in platforms like Kubernetes. It is designed to enhance the networking capabilities of container orchestration systems by offering features such as load balancing, service discovery, and security enforcement.</p>

<p>In the context of Kubernetes, Cilium serves as a networking and security solution that leverages the Linux kernel’s eBPF (extended Berkeley Packet Filter) technology. eBPF is a powerful and flexible in-kernel execution environment that allows the dynamic insertion of custom code into the Linux kernel without modifying its source.</p>

<p>Here are some key aspects of Cilium in relation to Kubernetes:</p>

<ul>
  <li><strong>Networking</strong>: Cilium provides efficient and high-performance networking for containerized workloads. It supports features like load balancing, network visibility, and fine-grained network policies.</li>
  <li><strong>Security</strong>: Cilium enhances security by using eBPF to enforce network security policies at the kernel level. This allows for the implementation of fine-grained security policies based on factors such as application identity and context.</li>
  <li><strong>Load Balancing</strong>: Cilium includes load balancing capabilities that help distribute traffic across services, ensuring high availability and optimal performance.</li>
  <li><strong>Service Discovery</strong>: Cilium aids in service discovery by providing mechanisms for applications to discover and connect to each other dynamically within the Kubernetes cluster.</li>
  <li><strong>API-Aware Network Security</strong>: Cilium allows for the creation of security policies based on the API and application layer information. This enables the definition of security rules that consider the specific requirements of applications.</li>
  <li><strong>Integration with Kubernetes</strong>: Cilium integrates seamlessly with Kubernetes and is often used as a replacement for the default Kubernetes networking solution (e.g., kube-proxy) to provide additional features and improvements.</li>
</ul>

<p>By leveraging <strong>eBPF</strong>, Cilium is able to achieve these functionalities with low overhead and high efficiency. It is worth noting that the Kubernetes ecosystem is dynamic, and the capabilities of projects like Cilium may evolve over time. Always refer to the official documentation and community resources for the most up-to-date information.</p>

<div id="what-is-hubble" />

<h3 id="what-is-hubble">What is Hubble?</h3>

<p>Hubble is a network visibility and monitoring tool that is closely associated with Cilium. It is part of the Cilium project and is designed to provide real-time visibility into the network traffic within a Cilium-enabled Kubernetes cluster. Hubble leverages the eBPF (extended Berkeley Packet Filter) technology to capture and analyze network events at the kernel level, allowing for detailed insights into the communication between services and workloads.</p>

<p>Key features and aspects of Hubble in relation to Cilium and Kubernetes include:</p>

<ul>
  <li><strong>Real-time Visibility</strong>: Hubble provides real-time visibility into the network communication between microservices and containers within a Kubernetes cluster. This visibility includes information about network flows, latencies, and error rates.</li>
  <li><strong>Topology Mapping</strong>: Hubble generates topology maps that illustrate the relationships and connections between different services and workloads in the cluster. These maps help administrators and developers understand the network architecture and dependencies.</li>
  <li><strong>Flow Tracing</strong>: Hubble allows for the tracing of network flows, enabling the visualization of the entire path taken by a packet as it traverses the network. This feature is valuable for troubleshooting and understanding the network behavior of applications.</li>
  <li><strong>Security Insights</strong>: By capturing and analyzing network events, Hubble can contribute to security insights by providing information about communication patterns and potential anomalies. This information can be useful for identifying and responding to security incidents.</li>
  <li><strong>Integration with Cilium</strong>: Hubble is tightly integrated with Cilium and relies on Cilium’s eBPF-based networking and security capabilities. It complements Cilium’s features by offering a tool specifically focused on network visibility and monitoring.</li>
  <li><strong>Web UI and CLI</strong>: Hubble provides both a web-based user interface (UI) and a command-line interface (CLI) for interacting with and querying network visibility data. The UI offers a graphical representation of the network topology and flow information.</li>
</ul>

<p>Overall, Hubble enhances the observability and troubleshooting capabilities of a Cilium-enabled Kubernetes environment. It is part of the broader ecosystem of tools and features provided by Cilium to address networking, security, and observability challenges in containerized environments. Keep in mind that the specifics of Hubble’s features and capabilities may evolve, so it’s advisable to refer to the official documentation and community resources for the latest information.</p>

<div id="prerequisites" />

<h2 id="prerequisites">Prerequisites</h2>

<p>In order to follow this guide, there are a few prerequisites that need to be met. Thes include: networking, kernel configuration, security settings, storage configuration, DNS, and a few other things.</p>

<div id="networking-pre-requisites" />

<h3 id="networking-pre-requisites">Networking Pre-Requisites</h3>

<p>Since we will be using cilium (eBPF) as the CNI, we will not need to configure iptables at all. However, packets must be forwaded and a couple kernel modules need to be enabled:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo modprobe br_netfilter</span>
<span class="s">sudo modprobe overlay</span>
<span class="s">sudo su -</span>
<span class="s">cat &lt;&lt;EOT | sudo tee /etc/modules-load.d/kubernetes.conf</span>
<span class="s">br_netfilter</span>
<span class="s">overlay</span>
<span class="s">EOT</span>
<span class="s">cat &lt;&lt;EOT | sudo tee /etc/sysctl.d/kubernetes.conf</span>
<span class="s">net.bridge.bridge-nf-call-ip6tables = </span><span class="m">1</span>
<span class="s">net.bridge.bridge-nf-call-iptables = </span><span class="m">1</span>
<span class="s">net.ipv4.ip_forward = </span><span class="m">1</span>
<span class="s">EOT</span>
<span class="s">sysctl --system</span>
<span class="s">exit</span>
</code></pre></div></div>

<div id="kernel-configuration" />

<h3 id="kernel-configuration">Kernel Configuration</h3>

<p>Before installing Cilium, please ensure that your system meets the minimum requirements below. Most modern Linux distributions already do.</p>

<ul>
  <li>Hosts with either AMD64 or AArch64 architecture</li>
  <li>Linux kernel &gt;= 4.19.57 or equivalent (e.g., 4.18 on RHEL8)</li>
</ul>

<p>Even though Rocky Linux is a RHEL clone, and the default kernel is 4.18, we will be using the latest kernel available from the Rocky Linux kernel-ml repo. This is because the latest kernel has the latest security patches and bug fixes. To install the latest kernel, run the following commands:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo dnf -y upgrade --refresh</span>
<span class="s">sudo rpm --import https://www.elrepo.org/RPM-GPG-KEY-elrepo.org</span>
<span class="s">sudo dnf install https://www.elrepo.org/elrepo-release-8.el8.elrepo.noarch.rpm -y</span>
<span class="s">sudo dnf --enablerepo=elrepo-kernel install -y kernel-ml kernel-ml-core kernel-ml-headers kernel-ml-modules kernel-ml-modules-extra</span>
</code></pre></div></div>

<p>Now you must restart.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo reboot now</span>
</code></pre></div></div>

<p>After reboot, check the kernel version:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">uname -r</span>
</code></pre></div></div>

<div id="seclinux-configuration" />

<h3 id="selinux-configuration">selinux Configuration</h3>

<p>If you want to use selinux you must install container-selinux:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo dnf install -y container-selinux</span>
</code></pre></div></div>

<p>Otherwise (for starters I suggest not using selinux), SELinux must be disabled on the nodes. To do so, run the following commands:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo setenforce </span><span class="m">0</span>
<span class="s">sudo sed -i 's/^SELINUX=enforcing$/SELINUX=permissive/' /etc/selinux/config</span>
</code></pre></div></div>

<div id="firewall-configuration" />

<h3 id="firewall-configuration">Firewall Configuration</h3>

<p>If you are using firewalld, you will need to add the following rules:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">ALLOWED_PORTS=( 6443 9100 8080 4245 9345 6443 6444 10250 10259 10257 2379 2380 9796 19090 9090 6942 9091 4244 4240 80 443 9963 9964 8081 8082 7000 9001 6379 9121 8084 6060 6061 6062 9879 9890 9891 9892 9893 9962 9966 )</span> 
<span class="s">for i in "${ALLOWED_PORTS[@]}"</span>
<span class="s">do</span>
  <span class="s">sudo firewall-cmd --add-port=$i/tcp --permanent</span>
<span class="s">done</span>

<span class="s">sudo firewall-cmd --add-port=30000-32767/tcp --permanent</span>
<span class="s">sudo firewall-cmd --remove-icmp-block=echo-request --permanent</span>
<span class="s">sudo firewall-cmd --remove-icmp-block=echo-reply --permanent</span>
<span class="c1"># Since we are using Cilium with GENEVE as overlay, we need the following port too:</span>
<span class="c1"># UDP</span>
<span class="s">UDP_PORTS=( 8472 4789 6081 51871 53 55355 58467 41637 39291 38519 46190 )</span>
<span class="s">for i in "${UDP_PORTS[@]}"</span>
<span class="s">do</span>
  <span class="s">sudo firewall-cmd --add-port=$i/udp --permanent</span>
<span class="s">done</span>
<span class="s">sudo firewall-cmd --reload</span>
<span class="c1">### Ingress Controller specific ports</span>

<span class="c1">### To get DNS resolution working, simply enable Masquerading.</span>
<span class="s">sudo firewall-cmd --zone=public  --add-masquerade --permanent</span>

<span class="s">sudo firewall-cmd --zone=trusted --permanent --add-source=192.168.0.0/16</span>

<span class="c1">### Finally apply all the firewall changes</span>
<span class="s">sudo firewall-cmd --reload</span>
</code></pre></div></div>

<div id="storage-configuration" />

<h3 id="storage-configuration">Storage Configuration</h3>

<p>We will be using Longhorn and local storage for this guide. To use Longhorn, you need <code class="language-plaintext highlighter-rouge">iscii</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo su -</span>
<span class="s">yum install -y nano curl wget git tmux jq vim-common iscsi-initiator-utils</span>
<span class="s">echo "iscsi_tcp" &gt;/etc/modules-load.d/iscsi-tcp.conf</span>
<span class="s">systemctl enable iscsid --now</span>
<span class="s">systemctl start iscsid</span>

<span class="s">cat &lt;&lt;EOF&gt;&gt; /etc/NetworkManager/conf.d/rke2-canal.conf</span>
<span class="pi">[</span><span class="nv">keyfile</span><span class="pi">]</span>
<span class="s">unmanaged-devices=interface-name:cali*;interface-name:flannel*</span>
<span class="s">EOF</span>
<span class="s">systemctl reload NetworkManager</span>
<span class="s">exit</span>
</code></pre></div></div>

<p>This completes the prerequisites. Now we can install RKE2.</p>

<div id="rke2-installation" />

<h2 id="rke2-installation">RKE2 Installation</h2>

<div id="rke2-installation-control-plane" />

<h3 id="control-plane-node">Control Plane Node</h3>

<p>To beghin with, lets create a config file for RKE2. This will be used to configure the cluster. Take note that we are defining the cluster and service CIDR, which is required if we want to use Cilium Cluster Mesh (so that we have no collisions with the default CIDR of the cluster). We are also defining the <code class="language-plaintext highlighter-rouge">tls-sans</code> which is the IP address of the master node. This is required for the kubeconfig to work properly.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo su -</span>
<span class="s">mkdir -p /etc/rancher/rke2/</span>
<span class="s">cat &lt;&lt;EOF &gt; /etc/rancher/rke2/config.yaml</span>
<span class="na">write-kubeconfig-mode</span><span class="pi">:</span> <span class="s2">"</span><span class="s">0644"</span>
<span class="c1"># profile: "cis-1.5"</span>
<span class="na">selinux</span><span class="pi">:</span> <span class="no">false</span>
<span class="c1"># add ips/hostname of hosts and loadbalancer</span>
<span class="na">tls-sans</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s2">"</span><span class="s">c1cp1.kubula.internal"</span>
  <span class="pi">-</span> <span class="s2">"</span><span class="s">192.168.7.11"</span>
<span class="c1"># Make a etcd snapshot every day at 4am</span>
<span class="na">etcd-snapshot-schedule-cron</span><span class="pi">:</span> <span class="s2">"</span><span class="s">0</span><span class="nv"> </span><span class="s">4</span><span class="nv"> </span><span class="s">*</span><span class="nv"> </span><span class="s">*</span><span class="nv"> </span><span class="s">*"</span>
<span class="c1"># Keep 14 etcd snapshots</span>
<span class="na">etcd-snapshot-retention</span><span class="pi">:</span> <span class="m">14</span>
<span class="na">etcd-expose-metrics</span><span class="pi">:</span> <span class="no">true</span>
<span class="na">disable</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s">rke2-canal</span>
  <span class="pi">-</span> <span class="s">rke2-kube-proxy</span>
<span class="na">network</span><span class="pi">:</span>
  <span class="na">plugin</span><span class="pi">:</span> <span class="s">none</span>
<span class="na">disable-kube-proxy</span><span class="pi">:</span> <span class="no">true</span>
<span class="na">disable-cloud-controller</span><span class="pi">:</span> <span class="no">true</span>
<span class="na">cluster-cidr</span><span class="pi">:</span> <span class="s">10.42.0.0/16</span>
<span class="na">service-cidr</span><span class="pi">:</span> <span class="s">10.96.0.0/16</span>
<span class="s">EOF</span>
</code></pre></div></div>

<div id="download-install-rke2" />

<h4 id="download-and-install-rke2">Download and Install RKE2</h4>

<p>Now we can download and install RKE2. We will be using the latest release, which at the time of writing is <code class="language-plaintext highlighter-rouge">v1.28.3+rke2r2</code>. You can find the latest release <a href="https://api.github.com/repos/rancher/rke2/releases">here</a>. To download and install RKE2, run the following commands:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">curl -sfL https://get.rke2.io | sudo INSTALL_RKE2_CHANNEL=latest INSTALL_RKE2_TYPE="server" sh -</span>
</code></pre></div></div>

<p><em>Note</em>: you can specify the exact version by setting <code class="language-plaintext highlighter-rouge">INSTALL_RKE2_VERSION</code> to the version you want to install. After installing RKE2, make sure to add the following to the <code class="language-plaintext highlighter-rouge">dnf</code> configuration to prevent RKE2 from being updated by <code class="language-plaintext highlighter-rouge">dnf</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo su -</span>
<span class="s">echo "exclude=rke2-*" &gt;&gt; /etc/dnf/dnf.conf</span>
<span class="s">exit</span>
</code></pre></div></div>

<div id="start-rke2" />

<h4 id="start-rke2">Start RKE2</h4>

<p>Now we can start RKE2:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo systemctl enable rke2-server.service --now</span>
</code></pre></div></div>

<div id="install-cilium-cli" />

<h4 id="installation-cilium-cli">Installation Cilium CLI</h4>

<p>For this guide, we will be using the Cilium CLI to install Cilium. <em>Note</em> that this can be done via a Helm chart as well. To install the Cilium CLI, run the following commands:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">CILIUM_CLI_VERSION=$(curl -s https://raw.githubusercontent.com/cilium/cilium-cli/main/stable.txt)</span>
<span class="s">CLI_ARCH=amd64</span>
<span class="s">curl -L --fail --remote-name-all https://github.com/cilium/cilium-cli/releases/download/${CILIUM_CLI_VERSION}/cilium-linux-${CLI_ARCH}.tar.gz{,.sha256sum}</span>
<span class="s">sha256sum --check cilium-linux-${CLI_ARCH}.tar.gz.sha256sum</span>
<span class="s">sudo tar xzvfC cilium-linux-${CLI_ARCH}.tar.gz /usr/local/bin</span>
<span class="s">rm cilium-linux-${CLI_ARCH}.tar.gz{,.sha256sum}</span>
</code></pre></div></div>

<div id="verify-rke2" />

<h4 id="verify-rke2">Verify RKE2</h4>

<p>To verify that RKE2 is running, run the following command:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo systemctl status rke2-server.service</span>
</code></pre></div></div>

<p>We should also get the <code class="language-plaintext highlighter-rouge">KUBECONFIG</code> file that is generated by RKE2. This will be used to access the cluster. To get the <code class="language-plaintext highlighter-rouge">KUBECONFIG</code> file, run the following command:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">mkdir ~/.kube</span>
<span class="s">sudo cp /etc/rancher/rke2/rke2.yaml ~/.kube/config</span>
<span class="s">sudo chown $(id -u):$(id -g) ~/.kube/config</span>
<span class="s">chmod 600 ~/.kube/config</span>

<span class="s">sudo cp /var/lib/rancher/rke2/bin/kubectl /usr/local/bin</span>
<span class="s">sudo chown $(id -u):$(id -g) /usr/local/bin/kubectl</span>
</code></pre></div></div>

<p>Now we can verify that the cluster is running:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl get nodes</span>
</code></pre></div></div>

<p><em>Note</em>: Because no CNI is installed, we should see that the nodes are in <code class="language-plaintext highlighter-rouge">NotReady</code> state.</p>

<div id="install-cilium" />

<h2 id="install-cilium">Install Cilium</h2>

<p>Now lets install Cilium. We will be using the Cilium CLI to install Cilium. In order to move all configuration options into a single file, we will be using a <code class="language-plaintext highlighter-rouge">cilium.yaml</code> file. This file will be used to configure Cilium. To create the <code class="language-plaintext highlighter-rouge">cilium.yaml</code> file, run the following command:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cat &lt;&lt;EOF &gt; cilium.yaml</span>
<span class="na">cluster</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">smig-cluster1</span>
  <span class="na">id</span><span class="pi">:</span> <span class="m">11</span>
<span class="na">prometheus</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">serviceMonitor</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">false</span>
<span class="na">dashboards</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
<span class="na">hubble</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">dns:query;ignoreAAAA</span>
    <span class="pi">-</span> <span class="s">drop</span>
    <span class="pi">-</span> <span class="s">tcp</span>
    <span class="pi">-</span> <span class="s">flow</span>
    <span class="pi">-</span> <span class="s">icmp</span>
    <span class="pi">-</span> <span class="s">http</span>
    <span class="na">dashboards</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">relay</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">prometheus</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">ui</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">baseUrl</span><span class="pi">:</span> <span class="s2">"</span><span class="s">/"</span>
<span class="na">version</span><span class="pi">:</span> <span class="s">1.14.3</span>
<span class="na">operator</span><span class="pi">:</span>
  <span class="na">prometheus</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">dashboards</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
<span class="c1"># clustermesh:</span>
<span class="c1">#   # -- Deploy clustermesh-apiserver for clustermesh</span>
<span class="c1">#   useAPIServer: false</span>
<span class="s">EOF</span>
</code></pre></div></div>

<p>Now we can install Cilium:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cilium install -f cilium.yaml</span>
</code></pre></div></div>

<div id="verify-cilium" />

<h3 id="verify-cilium">Verify Cilium</h3>

<p>Now we can verify that Cilium is running:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cilium status</span>
</code></pre></div></div>

<p>And we can verify that the nodes are ready:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl get nodes</span>
</code></pre></div></div>

<p>Now you should see the node as <code class="language-plaintext highlighter-rouge">Ready</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">NAME     STATUS   ROLES    AGE   VERSION</span>
<span class="s">c1cp1    Ready    master   10m   v1.28.3+rke2r2</span>
</code></pre></div></div>

<p>It is important that you also test connectivity with Cilum:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cilium hubble port-forward &amp;</span> <span class="c1">#3855849</span>
<span class="s">cilium connectivity test --force-deploy</span>
</code></pre></div></div>

<div id="worker-nodes" />

<h2 id="worker-nodes">Worker Nodes</h2>

<p>Once the controlplane is functional, we can install the and configure the RKE2 agent on the worker node(s). Until the exact confiruation/prerequisites are exported to a <code class="language-plaintext highlighter-rouge">VHDX</code> or encapsulated in Terraform/Ansible automation, please ensure that all aforementioned prerequisite steps are done on the worker VMs.</p>

<p>First, we need to get the token from the controlplane node:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">TOKEN=$(ssh -i ~/.ssh/rke2 -o IdentitiesOnly=yes master@192.168.7.11 sudo cat /var/lib/rancher/rke2/server/node-token)</span>
</code></pre></div></div>

<p>Now we need to create the configuration file for the RKE2 agent. To do this, run the following commands:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">```</span><span class="s">yaml</span>
<span class="s">sudo su -</span>
<span class="s">mkdir -p /etc/rancher/rke2/</span>
<span class="s">cat &lt;&lt;EOF &gt; /etc/rancher/rke2/config.yaml</span>
<span class="na">server</span><span class="pi">:</span> <span class="s">https://192.168.1.175:9345</span>
<span class="na">token</span><span class="pi">:</span> <span class="s">${TOKEN}</span>
<span class="s">EOF</span>
<span class="s">exit</span>
</code></pre></div></div>

<p>Now intall RKE2:</p>

<pre><code class="language-base">curl -sfL https://get.rke2.io | sudo INSTALL_RKE2_CHANNEL=latest INSTALL_RKE2_TYPE="agent" sh -
</code></pre>

<p><em>Note</em>: you can specify the exact version by setting <code class="language-plaintext highlighter-rouge">INSTALL_RKE2_VERSION</code> to the version you want to install. After installing RKE2, make sure to add the following to the <code class="language-plaintext highlighter-rouge">dnf</code> configuration to prevent RKE2 from being updated by <code class="language-plaintext highlighter-rouge">dnf</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo su -</span>
<span class="s">echo "exclude=rke2-*" &gt;&gt; /etc/dnf/dnf.conf</span>
<span class="s">exit</span>
</code></pre></div></div>

<p>Now we can start RKE2:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo systemctl enable rke2-agent.service --now</span>
</code></pre></div></div>

<div id="verify-rke2-agent" />

<h3 id="verify-rke2-agent">Verify RKE2 Agent</h3>

<p>To verify that RKE2 is running, run the following command:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">sudo systemctl status rke2-agent.service</span>
</code></pre></div></div>

<p>You can check the pods on the controlplane node to see if the agent has joined the cluster, and in the <code class="language-plaintext highlighter-rouge">kube-system</code> namespace the status of the <code class="language-plaintext highlighter-rouge">cilium-operator</code>. This operator will perform the installation of Cilium on the agent node. Once complete, the agent node will be ready.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl get nodes</span>
</code></pre></div></div>

<div id="metallb" />

<h2 id="metallb">MetalLB</h2>

<div id="what-is-metallb" />

<h3 id="what-is-metallb">What is MetalLB?</h3>

<p>MetalLB is an open-source, community-driven project that provides a load balancer implementation for bare-metal Kubernetes clusters. In a typical Kubernetes deployment, cloud providers often offer load balancing services that can be easily integrated with Kubernetes to distribute traffic to the appropriate pods. However, when running Kubernetes on bare metal, which means without the assistance of a cloud provider’s load balancing service, an external load balancer is needed to expose services to the external network.</p>

<p>Here are some key aspects of MetalLB in relation to Kubernetes:</p>

<ul>
  <li><strong>Load Balancing for Bare Metal</strong>: MetalLB is specifically designed to address the need for load balancing in bare-metal Kubernetes clusters. It provides a network load balancer implementation that can be used to expose services externally, just like you would in a cloud environment.</li>
  <li><strong>Layer 2 and BGP Modes</strong>: MetalLB supports two operation modes: Layer 2 (L2) mode and Border Gateway Protocol (BGP) mode. In L2 mode, MetalLB operates in the data link layer, using ARP (Address Resolution Protocol) to respond to service IP requests. In BGP mode, MetalLB advertises service IP addresses to the network using the BGP routing protocol.
<strong>Integration with Kubernetes Services</strong>: MetalLB integrates with Kubernetes services and automatically assigns and manages external IP addresses for services of type LoadBalancer. This allows services to be accessed from outside the cluster using the assigned external IP.
<strong>Configuration and Customization</strong>: MetalLB is configurable, allowing users to customize the behavior based on their specific requirements. Users can define pools of IP addresses that MetalLB can allocate from, and they can choose between the Layer 2 and BGP modes based on their network setup.</li>
  <li><strong>High Availability</strong>: MetalLB can be configured for high availability by running multiple instances in the cluster, ensuring that if one instance goes down, another can take over.</li>
</ul>

<p>Using MetalLB in a bare-metal Kubernetes environment enables users to take advantage of load balancing for their services, which is essential for applications that need to be accessed from outside the cluster. It’s particularly useful in scenarios where a cloud provider’s load balancing services are not available.</p>

<div id="install-metallb" />

<h3 id="intall-metallb">Intall MetalLB</h3>

<p>To install MetalLB, we will use Helm. First, we need to add the Helm repository:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm repo add metallb https://metallb.github.io/metallb</span>
<span class="s">helm install metallb metallb/metallb</span>
</code></pre></div></div>

<p>You can now install MetalLB:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">helm install --namespace metallb-system metallb metallb/metallb</span>
</code></pre></div></div>

<p>The easiest way to use MetalLB is to configure networking at layer 2. Under this approach, you simply assign a range of IP addresses to MetalLB. It then automatically assigns them nodes and manages traffic between them and your endpoints.</p>

<p>To define the address pool, open the MetalLB ConfigMap with:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl edit configmap config -n metallb-system</span>
</code></pre></div></div>

<p>Then define the address-pools and addresses values as desired. For example, to use the range 192.168.255.1–192.168.255.255, set the configuration to:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">ConfigMap</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">metallb-system</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">config</span>
<span class="na">data</span><span class="pi">:</span>
  <span class="na">config</span><span class="pi">:</span>
    <span class="na">address-pools</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">default</span>
    <span class="na">protocol</span><span class="pi">:</span> <span class="s">layer2</span>
      <span class="s">addresses</span><span class="err">:</span>
      <span class="pi">-</span> <span class="s">192.168.8.1-192.168.8.255</span>
</code></pre></div></div>

<p>After making changes, apply them with:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl rollout restart deployment controller -n metallb-system</span>
</code></pre></div></div>

<div id="verify-metallb" />

<h3 id="verify-metallb">Verify MetalLB</h3>

<p>To verify that MetalLB is running, run the following command:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl get pods -n metallb-system</span>
</code></pre></div></div>

<div id="cilium-clustermesh" />

<h2 id="cilium-cluster-mesh">Cilium Cluster Mesh</h2>

<p>Cilium Cluster Mesh allows you to connect the networks of multiple clusters in such as way that pods in each cluster can discover and access services in all other clusters of the mesh, provided all the clusters run Cilium as their CNI. This allows effectively joining multiple clusters into a large unified network, regardless of the Kubernetes distribution or location each of them is running. This is achieved by leveraging the Cilium Identity feature to assign a unique identity to each pod, and using that identity to establish secure connections between pods in different clusters. Furthermore, global services can be defined to expose services across the entire mesh to further improve HA. This is a great way to connect multiple clusters together, and it’s very easy to set up.</p>

<p>In this guide we have two clusters, <code class="language-plaintext highlighter-rouge">smig-cluster1</code> and <code class="language-plaintext highlighter-rouge">smig-cluster2</code>. We will use <code class="language-plaintext highlighter-rouge">smig-cluster1</code> as the primary cluster, and <code class="language-plaintext highlighter-rouge">smig-cluster2</code> as the secondary cluster. We will connect <code class="language-plaintext highlighter-rouge">smig-cluster2</code> to <code class="language-plaintext highlighter-rouge">smig-cluster1</code>. To do this, we need to copy over the <code class="language-plaintext highlighter-rouge">KUBECONFIG</code> file from <code class="language-plaintext highlighter-rouge">smig-cluster1</code> to our local machine, and then copy it over to <code class="language-plaintext highlighter-rouge">smig-cluster2</code>. <em>Note</em> that you when merging the <code class="language-plaintext highlighter-rouge">KUBECONFIG</code> files, you need to make sure that the <code class="language-plaintext highlighter-rouge">clusters</code> and <code class="language-plaintext highlighter-rouge">contexts</code> sections are unique, but more importantly update the <code class="language-plaintext highlighter-rouge">server</code> value in the <code class="language-plaintext highlighter-rouge">clusters</code> section to point to the IP address of the corresponding cluster control plane.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">CLUSTER1=smig-cluster1</span>
<span class="s">CLUSTER2=smig-cluster2</span>

<span class="c1"># In order for cluster mesh to work properly, the same CA secret must exist in both clusters. Therefore delete the secret in cluster 2 and recreate it from cluster 1.</span>
<span class="s">kubectl --context=$CLUSTER2 delete secret -n kube-system cilium-ca</span>
<span class="s">kubectl --context=$CLUSTER1 get secret -n kube-system cilium-ca -o yaml | \</span>
  <span class="s">kubectl --context $CLUSTER2 create -f -</span>

<span class="s">cilium clustermesh enable --context $CLUSTER1 --service-type ClusterIP</span>
<span class="s">cilium clustermesh enable --context $CLUSTER2 --service-type ClusterIP</span>


<span class="s">cilium clustermesh connect --context $CLUSTER1 --destination-context $CLUSTER2</span>
<span class="s">cilium clustermesh connect --context $CLUSTER2 --destination-context $CLUSTER1</span>
</code></pre></div></div>

<h2 id="create-servicemonitors">Create ServiceMonitors</h2>

<p>When you have <code class="language-plaintext highlighter-rouge">Prometheus</code> installed, you can enable the Cilium <code class="language-plaintext highlighter-rouge">ServiceMonitor</code> to scrape metrics from Cilium. This is done by creating a ServiceMonitor resource in the <code class="language-plaintext highlighter-rouge">monitoring-system</code> namespace. The <code class="language-plaintext highlighter-rouge">ServiceMonitor</code> resource is defined in the <code class="language-plaintext highlighter-rouge">monitoring-system</code> namespace, and it will automatically discover the Cilium pods and scrape metrics from them. To create the ServiceMonitor, use the cilium CLI (or Helm chart) to update the Cilium installation, using the below configuration:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cat &lt;&lt;EOF &gt; cilium-upgrade.yaml</span>
<span class="na">hubble</span><span class="pi">:</span>
  <span class="na">metrics</span><span class="pi">:</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">dashboards</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
  <span class="na">relay</span><span class="pi">:</span>
    <span class="na">prometheus</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">serviceMonitor</span><span class="pi">:</span>
        <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
        <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
<span class="na">prometheus</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">serviceMonitor</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
<span class="na">envoy</span><span class="pi">:</span>
  <span class="na">prometheus</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
<span class="na">operator</span><span class="pi">:</span>
  <span class="na">prometheus</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">serviceMonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
  <span class="na">dashboards</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
<span class="na">clustermesh</span><span class="pi">:</span>
  <span class="na">apiserver</span><span class="pi">:</span>
    <span class="na">metrics</span><span class="pi">:</span>
      <span class="na">serviceMonitor</span><span class="pi">:</span>
        <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
        <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
<span class="na">dashboards</span><span class="pi">:</span>
  <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">monitoring-system</span>
<span class="s">EOF</span>
</code></pre></div></div>

<p>Then run the following command to apply the changes:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">cilium upgrade -f cilium-upgrade.yaml</span>
</code></pre></div></div>

<h2 id="verify-cilium-servicemonitor">Verify Cilium ServiceMonitor</h2>

<p>To verify that the Cilium ServiceMonitor is running, run the following command:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl get servicemonitor -n monitoring-system</span>
</code></pre></div></div>

<p>You should see the following <code class="language-plaintext highlighter-rouge">ServiceMonitor</code> resources (among others)):</p>

<ul>
  <li>cilium-agent</li>
  <li>cilium-operator</li>
  <li>hubble</li>
</ul>

<p>You can also verify this if you go to the Prometheus UI and click on <code class="language-plaintext highlighter-rouge">Status</code> -&gt; <code class="language-plaintext highlighter-rouge">Targets</code>. You should see the above resources listed and ensure that they are in the <code class="language-plaintext highlighter-rouge">Up</code> state.</p>

<p>This will also create a couple Grafana dashboard for Cilium and Hubble. They will be stored in <code class="language-plaintext highlighter-rouge">ConfigMap</code>s in the <code class="language-plaintext highlighter-rouge">monitoring-system</code> namespace. To view the dashboards, you can use port-forwarding to access the Grafana UI:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">kubectl port-forward -n monitoring-system svc/prometheus-stack-grafana 3000:80</span>
</code></pre></div></div>

<p>Then open your browser and go to <code class="language-plaintext highlighter-rouge">http://localhost:3000</code>. You should see the Grafana UI. Click on <code class="language-plaintext highlighter-rouge">Explore</code> and you should see the Cilium and Hubble dashboards.</p>]]></content><author><name>Mitch Murphy</name></author><category term="rke2" /><category term="cilium. hubble" /><category term="kubernetes" /><category term="mesh" /><category term="cluster" /><summary type="html"><![CDATA[Howto guide for setting up RKE2 with Cilium, Hubble and Cluster Mesh]]></summary></entry><entry><title type="html">Setting up a 5 node K3s Cluster on Raspberry Pi’s</title><link href="https://mitchmurphy.io/k3s-raspberry-pi/" rel="alternate" type="text/html" title="Setting up a 5 node K3s Cluster on Raspberry Pi’s" /><published>2021-10-15T00:00:00-04:00</published><updated>2021-10-15T00:00:00-04:00</updated><id>https://mitchmurphy.io/k3s-raspberry-pi</id><content type="html" xml:base="https://mitchmurphy.io/k3s-raspberry-pi/"><![CDATA[<h1 id="how-to-guide-home-kubernetes-cluster">How to Guide: Home Kubernetes Cluster</h1>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Title</span><span class="pi">:</span> <span class="s">Setting up K3s on Raspberry Pi's and Jetson Nano's</span>
<span class="na">Author</span><span class="pi">:</span> <span class="s">Mitch Murphy</span>
<span class="na">Date</span><span class="pi">:</span> <span class="s">2021-10-09</span>
</code></pre></div></div>

<hr />

<h2 id="table-of-contents">Table of contents</h2>

<ol>
  <li><a href="#introduction">Introduction</a></li>
  <li><a href="#materials">Materials</a>
    <ol>
      <li><a href="operating-systems">Operating Systems</a></li>
      <li><a href="#disk-pperation-speeds">Disk Operation Speeds</a></li>
    </ol>
  </li>
  <li><a href="#prerequisites">Prerequisites</a>
    <ol>
      <li><a href="#static-ips">Static IPs</a></li>
      <li><a href="#ssh">SSH</a></li>
    </ol>
  </li>
  <li><a href="#mount-storage-volume">Mount Storage Volume</a></li>
  <li><a href="#install-k3s">Install K3s</a>
    <ol>
      <li><a href="#k3s-master">K3s Master</a></li>
    </ol>
  </li>
  <li><a href="#helm">Helm</a>
    <ol>
      <li><a href="#add-helm-repos">Add Helm Repos</a></li>
    </ol>
  </li>
  <li><a href="#dashboard">Dashboard</a>
    <ol>
      <li><a href="#deploying-the-dashboard">Deploying the Dashboard</a></li>
      <li><a href="#access-dashboard">Access Dashboard</a></li>
    </ol>
  </li>
  <li><a href="#workers">Workers</a>
    <ol>
      <li><a href="#worker-1">Worker 1</a></li>
      <li><a href="#install-agent">Install Agent</a></li>
    </ol>
  </li>
  <li><a href="#add-private-registry">Add Private Registry</a></li>
  <li><a href="#gpu-support">GPU Support</a>
    <ol>
      <li><a href="#swap">Swap</a></li>
      <li><a href="#disable-ipv6">Disable IPv6</a></li>
      <li><a href="#assign-static-ip">Assign Static IP</a></li>
      <li><a href="#deploy-k3s">Deploy K3s</a></li>
      <li><a href="#container-configuration">Container Configuration</a></li>
      <li><a href="#test-gpu-support">Test GPU Support</a></li>
      <li><a href="#pytorch">PyTorch</a></li>
      <li><a href="#gan">GAN</a></li>
    </ol>
  </li>
</ol>

<h2 id="introduction">Introduction</h2>

<p>In this article we will be setting up a 5 node K3s cluster: one control plane, three workers (Raspberry Pis) and one GPU worker (Nvidia Jetson Nano) to enable GPU workloads such as Tensorflow. Let’s get started.</p>

<h2 id="materials">Materials</h2>

<p>This is a pretty cost effective cluster (for the computational power at least), here is what I will be using:</p>

<ul>
  <li>2 x <a href="https://www.cytron.io/p-raspberry-pi-4-model-b-8gb">Raspberry Pi 4 Model B - 8GB</a> - $87.25</li>
  <li>2 x <a href="https://www.cytron.io/p-raspberry-pi-4-model-b-4gb">Raspberry Pi 4 Model B - 4GB</a> - $59.75</li>
  <li>1 x <a href="https://www.amazon.com/NVIDIA-Jetson-Nano-Developer-945-13450-0000-100/dp/B084DSDDLT">Nvidia Jetson Nano 4GB</a> - $169.99</li>
  <li>4 x <a href="https://www.amazon.com/gp/product/B0786QNS9B">Crucial MX500 500GB SSD</a> - $54.99</li>
  <li>4 x <a href="https://www.amazon.com/gp/product/B011M8YACM">SATA/SSD to USB Adapter</a> - $9.99</li>
  <li>1 x <a href="https://www.amazon.com/gp/product/B08LH5SX4V/">1ft USB C Cables, 5 pack</a> - $8.99</li>
  <li>1 x <a href="https://www.amazon.com/gp/product/B08HN6JK7N">USB Charging Station - 60W, 12A</a> - $27.99</li>
  <li>1 x <a href="https://www.amazon.com/gp/product/B00C4U030G">1ft CAT 6 Cables, 5 pack</a> - $10.99</li>
  <li>1 x <a href="https://www.amazon.com/gp/product/B07PFYM5MZ">NETGEAR Ethernet Switch</a> - $19.99</li>
  <li>1 x <a href="https://www.amazon.com/gp/product/B08FH3V6GV">Raspberry Pi Cluster Case</a> - $84.99</li>
</ul>

<p><em>Notes</em>:</p>

<p>That the Nvidia Jetson Nano was only $99.99 when I bought it, the same model with 4GB of RAM is now 169.99, there is a 2GB version on <a href="https://www.amazon.com/NVIDIA-Jetson-Nano-Developer-945-13541-0000-000/dp/B08J157LHH">Amazon</a> for $59.00. Furthermore, I have decided to attach separate storage volumes (SSD) to each node, this is for two reasons: I would like to run a full media server on the cluster and ML/AI workloads are data intensive and read/write speeds on SD cards are not great. Both of these are completely optional.</p>

<p>This brings the total cost to build this exact cluster at <strong>$848.87</strong>.</p>

<h3 id="operating-systems">Operating Systems</h3>

<p>For this build, all of the Raspberry Pi’s will be using <code class="language-plaintext highlighter-rouge">Ubuntu 20.04.3 LTS (Focal Fossa)</code>. Nvidia provides it’s own image, <code class="language-plaintext highlighter-rouge">Ubuntu 18.04.6 LTS</code>, which can be found <a href="https://developer.nvidia.com/jetson-nano-sd-card-image">here</a>.</p>

<h3 id="disk-operation-speeds">Disk Operation Speeds</h3>

<p>You can determine the storage speeds using the <code class="language-plaintext highlighter-rouge">dd</code> command, as so:</p>

<p><strong>Read</strong>:</p>

<figure class="highlight"><pre><code class="language-bash" data-lang="bash"><span class="nb">dd </span><span class="k">if</span><span class="o">=</span>./speedTestFile <span class="nv">of</span><span class="o">=</span>/dev/zero <span class="nv">bs</span><span class="o">=</span>20M <span class="nv">count</span><span class="o">=</span>5 <span class="nv">oflag</span><span class="o">=</span>dsync <span class="c"># for SD card</span>
<span class="nb">dd </span><span class="k">if</span><span class="o">=</span>/mnt/storage/speedTestFile <span class="nv">of</span><span class="o">=</span>/dev/zero <span class="nv">bs</span><span class="o">=</span>20M <span class="nv">count</span><span class="o">=</span>5 <span class="nv">oflag</span><span class="o">=</span>dsync <span class="c"># for SSD</span></code></pre></figure>

<p><strong>Write</strong>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">dd </span><span class="k">if</span><span class="o">=</span>/dev/zero <span class="nv">of</span><span class="o">=</span>./speedTestFile <span class="nv">bs</span><span class="o">=</span>20M <span class="nv">count</span><span class="o">=</span>5 <span class="nv">oflag</span><span class="o">=</span>direct <span class="c"># for SD card</span>
<span class="nb">sudo dd </span><span class="k">if</span><span class="o">=</span>/dev/zero <span class="nv">of</span><span class="o">=</span>/mnt/storage/speedTestFile <span class="nv">bs</span><span class="o">=</span>20M <span class="nv">count</span><span class="o">=</span>5 <span class="nv">oflag</span><span class="o">=</span>direct <span class="c"># for SSD</span>
</code></pre></div></div>

<table>
  <thead>
    <tr>
      <th>Device</th>
      <th>Read (mb/s)</th>
      <th>Write (mb/s)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>SD Card</td>
      <td>39.7</td>
      <td>19.3</td>
    </tr>
    <tr>
      <td>SSD</td>
      <td>280.0</td>
      <td>221.0</td>
    </tr>
  </tbody>
</table>

<h2 id="prerequisites">Prerequisites</h2>

<p>Login! <code class="language-plaintext highlighter-rouge">ssh ubuntu@&lt;IPADDR&gt;</code> and use the default password of <code class="language-plaintext highlighter-rouge">ubuntu</code>. It will require you to change this. We will be disabling this account next.</p>

<blockquote>
  <p>Create user: <code class="language-plaintext highlighter-rouge">sudo adduser master</code><br />
Add groups: <code class="language-plaintext highlighter-rouge">sudo usermod -a -G adm,dialout,cdrom,floppy,sudo,audio,dip,video,plugdev,netdev,lxd master</code></p>
</blockquote>

<p>Now logout and log back in: <code class="language-plaintext highlighter-rouge">ssh master@&lt;IPADDR&gt;</code> and then delete the default user: <code class="language-plaintext highlighter-rouge">sudo deluser --remove-home ubuntu</code>.</p>

<p>It time to rename our nodes. I will be naming master node as k3s-master and similarly worker nodes as k3s-worker to k3s-worker3. Change the hostname with: <code class="language-plaintext highlighter-rouge">sudo hostnamectl set-hostname k3s-master</code>.</p>

<p>We are going to update our installation, so we have latest and greatest packages by running: <code class="language-plaintext highlighter-rouge">sudo apt update &amp;&amp; sudo apt upgrade -y</code>. Now reboot.</p>

<p>As cloud-init is present on this image we are going to edit also: <code class="language-plaintext highlighter-rouge">sudo nano /etc/cloud/cloud.cfg</code>. Change <code class="language-plaintext highlighter-rouge">preserve_hostname</code> to <code class="language-plaintext highlighter-rouge">true</code>. Reboot again.</p>

<h3 id="static-ips">Static IPs</h3>

<p>In order for our nodes in our cluster to properly communicate with each other, we need to set static IP addresses to each node. The easiest way of doing this (for a home cluster) is by adding this entry to <code class="language-plaintext highlighter-rouge">/etc/netplan/50-cloud-init.yaml</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>network:
    ethernets:
        eth0:
            dhcp4: no
            addresses: <span class="o">[</span>&lt;STATIC_IP&gt;/24]
            gateway4: &lt;GATEWAY_ADDRESS&gt;
            nameservers:
              addresses: <span class="o">[</span>8.8.8.8,8.8.4.4]
    version: 2
</code></pre></div></div>

<p><em>Note</em> that this process differs for the Nvidia Jetson Nano, which can be found <a href="#assign-static-ip">below</a>. Reboot and run <code class="language-plaintext highlighter-rouge">hostname -I</code> to cofirm the changes.</p>

<h3 id="install-docker">Install Docker</h3>

<p>Docker needs to be installed in order to run the K3s install script. Perform the following:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>apt upgrade
<span class="nb">sudo </span>apt update <span class="nt">-y</span>
curl <span class="nt">-fsSL</span> https://get.docker.com <span class="nt">-o</span> get-docker.sh
<span class="nb">sudo </span>sh get-docker.sh
</code></pre></div></div>

<p>In order to run Docker as a non-root user you must add the current user to the Docker group with <code class="language-plaintext highlighter-rouge">sudo usermod -aG docker $USER</code></p>

<h3 id="ssh">SSH</h3>

<p>It is good practice to disable username/password SSH login, this is done by editing <code class="language-plaintext highlighter-rouge">sudo nano /etc/ssh/sshd_config</code>, as so:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>From:
<span class="c">#PermitRootLogin prohibit-password</span>
<span class="c">#PasswordAuthentication yes</span>
<span class="c">#PubkeyAuthentication yes</span>
To:
PermitRootLogin no
PasswordAuthentication no
PubkeyAuthentication <span class="nb">yes</span>
</code></pre></div></div>

<p>After making the change, validate that we have no errors and restart SSH daemon.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo</span> /usr/sbin/sshd <span class="nt">-t</span>
<span class="nb">sudo </span>systemctl restart sshd.service
</code></pre></div></div>

<p>Before doing this, generate a local key pair with <code class="language-plaintext highlighter-rouge">ssh-keygen</code>, and then copy this to the server with <code class="language-plaintext highlighter-rouge">ssh-copy-id -i &lt;IDENTITY_FILE&gt; master@k3s-master</code>. Next, edit your <code class="language-plaintext highlighter-rouge">~/.ssh/config</code> file to reflect:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Host k3s-master
Hostname k3s-master
User master
IdentityFile ~/.ssh/id_k3s-master

Host k3s-worker1
Hostname k3s-worker1
User worker
IdentityFile ~/.ssh/id_k3s-worker1

Host k3s-worker2
Hostname k3s-worker2
User worker
IdentityFile ~/.ssh/id_k3s-worker2

Host k3s-worker-gpu
Hostname k3s-worker-gpu
User worker
IdentityFile ~/.ssh/id_k3s-worker-gpu
</code></pre></div></div>

<p>You should also update your <code class="language-plaintext highlighter-rouge">/etc/hosts</code> file:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>192.168.0.100   k3s-master
192.168.0.101   k3s-worker1
192.168.0.102   k3s-worker2
192.168.0.104   k3s-worker-gpu
</code></pre></div></div>

<p>Make sure you enable <code class="language-plaintext highlighter-rouge">cgroups</code> by editing <code class="language-plaintext highlighter-rouge">/boot/firmware/cmdline.txt</code>: add the following:</p>
<blockquote>
  <p><code class="language-plaintext highlighter-rouge">cgroup_enable=cpuset cgroup_enable=memory cgroup_memory=1</code></p>
</blockquote>

<p>Disable wireless/bluetooth by adding the following lines to <code class="language-plaintext highlighter-rouge">/boot/firmware/config.txt</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">dtoverlay</span><span class="o">=</span>disable-wifi
<span class="nv">dtoverlay</span><span class="o">=</span>disable-bluetooth
</code></pre></div></div>

<p>You also need to disable IPv6. Add the following lines to <code class="language-plaintext highlighter-rouge">/etc/sysctl.conf</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>net.ipv6.conf.all.disable_ipv6<span class="o">=</span>1
net.ipv6.conf.default.disable_ipv6<span class="o">=</span>1
net.ipv6.conf.lo.disable_ipv6<span class="o">=</span>1
</code></pre></div></div>

<p>Reload: <code class="language-plaintext highlighter-rouge">sudo sysctl -p</code>. You may also need to create the following script at <code class="language-plaintext highlighter-rouge">/etc/rc.local</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c">#!/bin/bash</span>
<span class="c"># /etc/rc.local</span>

/etc/sysctl.d
/etc/init.d/procps restart

<span class="nb">exit </span>0
</code></pre></div></div>

<p>Change permissions on above file: <code class="language-plaintext highlighter-rouge">sudo chmod 755 /etc/rc.local</code>. Finally reboot to take effect with <code class="language-plaintext highlighter-rouge">sudo reboot</code>.</p>

<p>Rinse and repeat for all worker nodes. It is also advisable to do the same for communication among all the nodes (control planes and worker).</p>

<h2 id="mount-storage-volume">Mount Storage Volume</h2>

<p>While we are booting off an SD card (class 10), we wish to leverage the higher read/write speeds on a USB mounted SSD drive for storing any data. This was how I automounted the drives to a stanard mount point on each node.</p>

<ol>
  <li>Make sure you format each drive with the <code class="language-plaintext highlighter-rouge">ext4</code> type.</li>
  <li>Next create a folder on each node which will serve as the mount point at <code class="language-plaintext highlighter-rouge">/mnt/storage</code></li>
  <li>Get the UUID of the device you want to automount: <code class="language-plaintext highlighter-rouge">blkid</code></li>
  <li>Add the entry to <code class="language-plaintext highlighter-rouge">/etc/fstab</code>:
    <blockquote>
      <p><code class="language-plaintext highlighter-rouge">UUID=&lt;MY_UUID&gt; /mnt/storage ext4 defaults,auto,users,rw,nofail 0 0</code></p>
    </blockquote>
  </li>
</ol>

<h2 id="install-k3s">Install K3s</h2>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-sfL</span> https://get.k3s.io | <span class="nv">INSTALL_KUBE_EXEC</span><span class="o">=</span><span class="s2">"--write-kubeconfig-mode 664 </span><span class="se">\</span><span class="s2">
--bind-address 192.168.0.100 --advertise-address 192.168.0.100 </span><span class="se">\</span><span class="s2">
--default-local-storage-path /mnt/storage --cluster-init --node-label memory=high"</span> sh -
</code></pre></div></div>

<p><em>Note</em>: Here I add the <code class="language-plaintext highlighter-rouge">memory</code> label to each node, as this cluster will be comprised of 8gb, 4gb and 2gb nodes.</p>

<h3 id="k3s-master">K3s Master</h3>

<ul>
  <li>IPv4: <code class="language-plaintext highlighter-rouge">192.168.0.100</code></li>
  <li>Domain: <code class="language-plaintext highlighter-rouge">cluster.smigula.io</code></li>
  <li>User: <code class="language-plaintext highlighter-rouge">master</code></li>
  <li>Password: <code class="language-plaintext highlighter-rouge">&lt;PASSWD&gt;</code></li>
</ul>

<h2 id="helm">Helm</h2>

<p>First install Helm on the control plane:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># define what Helm version and where to install:</span>
<span class="nb">export </span><span class="nv">HELM_VERSION</span><span class="o">=</span>v3.7.0
<span class="nb">export </span><span class="nv">HELM_INSTALL_DIR</span><span class="o">=</span>/usr/local/bin

<span class="c"># download the binary and get into place:</span>
<span class="nb">cd</span> /tmp
wget https://get.helm.sh/helm-<span class="nv">$HELM_VERSION</span><span class="nt">-linux-arm64</span>.tar.gz
<span class="nb">tar </span>xvzf helm-<span class="nv">$HELM_VERSION</span><span class="nt">-linux-arm64</span>.tar.gz
<span class="nb">sudo mv </span>linux-arm64/helm <span class="nv">$HELM_INSTALL_DIR</span>/helm

<span class="c"># clean up:</span>
<span class="nb">rm</span> <span class="nt">-rf</span> linux-arm64 <span class="o">&amp;&amp;</span> <span class="nb">rm </span>helm-<span class="nv">$HELM_VERSION</span><span class="nt">-linux-arm64</span>.tar.gz
</code></pre></div></div>

<h3 id="add-helm-repos">Add Helm Repos</h3>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>helm repo add stable https://charts.helm.sh/stable
helm repo add bitnami https://charts.bitnami.com/bitnami
helm repo add rancher-latest https://releases.rancher.com/server-charts/latest
helm repo add jetstack https://charts.jetstack.io
</code></pre></div></div>

<h2 id="dashboard">Dashboard</h2>

<p>There is a default Kubernetes dashboard that we will be deploying; the dashboard is a web-based Kubernetes user interface. You can use Dashboard to deploy containerized applications to a Kubernetes cluster, troubleshoot your containerized application, and manage the cluster resources. The dashboard also provides information on the state of Kubernetes resources in your cluster and on any errors that may have occurred.</p>

<h3 id="deploying-the-dashboard-ui">Deploying the Dashboard UI</h3>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># this is necessary to address https://github.com/rancher/k3s/issues/1126 for now:</span>
<span class="nb">export </span><span class="nv">KUBECONFIG</span><span class="o">=</span>/etc/rancher/k3s/k3s.yaml <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">source</span> ~/.bashrc
</code></pre></div></div>

<p>I made some slight changes to the <a href="https://raw.githubusercontent.com/kubernetes/dashboard/v2.3.1/aio/deploy/recommended.yaml">official manifests</a> that Kubernetes provides (changed the service type, created a user/service account and cluster role bindings), which can be found <a href="manifests/dashboard.yaml">here</a>. Apply them: <code class="language-plaintext highlighter-rouge">kubectl apply -f https://raw.githubusercontent.com/mkm29/ai-on-the-edge/main/manifests/dashboard.yaml</code>.</p>

<h3 id="access-dashboard">Access Dashboard</h3>

<p>Currently the service is being exposed as a <code class="language-plaintext highlighter-rouge">NodePort</code> service, which can be accessed at <a href="https://cluster.smigula.io">https://cluster.smigula.io:30000</a>. In order to login, you first need to get a Bearer token from Kubernetes:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl <span class="nt">-n</span> kubernetes-dashboard get secret <span class="si">$(</span>kubectl <span class="nt">-n</span> kubernetes-dashboard get sa/admin-user <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s2">"{.secrets[0].name}"</span><span class="si">)</span> <span class="nt">-o</span> go-template<span class="o">=</span><span class="s2">""</span>
</code></pre></div></div>

<p><em>Note</em> that due to me using CloudFlare as free DDNS, there will be a TLS/cert issue. If you deploy this locally with no DDNS you should not run into this issue.</p>

<h2 id="workers">Workers</h2>

<h3 id="worker-1">Worker 1</h3>

<ul>
  <li>IPv4: <code class="language-plaintext highlighter-rouge">192.168.0.101</code></li>
  <li>Domain:</li>
  <li>User: <code class="language-plaintext highlighter-rouge">worker</code></li>
  <li>Password: <code class="language-plaintext highlighter-rouge">&lt;PASSWD&gt;</code></li>
</ul>

<p><strong>Token</strong> can be found at <code class="language-plaintext highlighter-rouge">/var/lib/rancher/k3s/server/token</code> on the control plane.</p>

<h3 id="install-agent">Install Agent</h3>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">export </span><span class="nv">TOKEN</span><span class="o">=</span>K10513ec520ffb7ce3d94da39d5a26be5da9324769f035498595c9941d21bcfeb62::server:ed7aefd846db06468a6c78fb91d461d2
curl <span class="nt">-sfL</span> https://get.k3s.io | <span class="nv">K3S_URL</span><span class="o">=</span>https://192.168.0.100:6443 <span class="nv">K3S_TOKEN</span><span class="o">=</span><span class="nv">$TOKEN</span> <span class="se">\</span>
  <span class="nv">INSTALL_KUBE_EXEC</span><span class="o">=</span><span class="s2">"--node-label memory=high"</span> sh -
</code></pre></div></div>

<h2 id="add-private-registry">Add Private Registry</h2>

<p>Create the file <code class="language-plaintext highlighter-rouge">/etc/rancher/k3s/registries.yaml</code>, and add the following to it:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>mirrors:
  <span class="s2">"docker.io"</span>:
    endpoint:
      - <span class="s2">"https://docker.io"</span>
configs:
  <span class="s2">"docker.io"</span>:
    auth:
      username: <span class="s2">"smigula"</span>
      password: &lt;TOKEN&gt;
    tls:
      insecure_skip_verify: <span class="nb">true</span>
</code></pre></div></div>

<p><em>Note</em>: you will need to do this for all worker nodes. Can this be added to the <code class="language-plaintext highlighter-rouge">/etc/rancher/k3s/nodes/</code> as an Ansible playbook?</p>

<h2 id="gpu-support">GPU Support</h2>

<p>This section will cover what is needed to configure a node (eg Nvidia Jetson Nano) to give containers access to a GPU.</p>

<ol>
  <li>Create user: <code class="language-plaintext highlighter-rouge">sudo useradd worker</code></li>
  <li>Set password: <code class="language-plaintext highlighter-rouge">sudo passwd worker</code></li>
  <li>Add groups to user: <code class="language-plaintext highlighter-rouge">sudo usermod -aG adm,cdrom,sudo,audio,dip,video,plugdev,i2c,lpadmin,gdm,sambashare,weston-launch,gpio worker</code></li>
</ol>

<h3 id="swap">Swap</h3>

<p>You need to set the swap size to 8gb, use the following script:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/JetsonHacksNano/resizeSwapMemory.git
<span class="nb">cd </span>resizeSwapMemory
<span class="nb">chmod</span> +x setSwapMemorySize.sh
./setSwapMemorySize.sh <span class="nt">-g</span> 8
</code></pre></div></div>

<h3 id="disable-ipv6">Disable IPv6</h3>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>sysctl <span class="nt">-w</span> net.ipv6.conf.all.disable_ipv6<span class="o">=</span>1
<span class="nb">sudo </span>sysctl <span class="nt">-w</span> net.ipv6.conf.default.disable_ipv6<span class="o">=</span>1
<span class="nb">sudo </span>sysctl <span class="nt">-w</span> net.ipv6.conf.lo.disable_ipv6<span class="o">=</span>1
</code></pre></div></div>

<h3 id="assign-static-ip">Assign Static IP</h3>

<ol>
  <li>Edit <code class="language-plaintext highlighter-rouge">sudo vi /etc/default/networking</code></li>
  <li>Set the parameter CONFIGURE_INTERFACES to no</li>
  <li><code class="language-plaintext highlighter-rouge">sudo vi /etc/network/interfaces</code></li>
</ol>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>auto eth0
iface eth0 inet static
  address 192.168.0.104
  netmask 255.255.255.0
  gateway 192.168.0.1
</code></pre></div></div>

<h3 id="deploy-k3s">Deploy K3s</h3>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">export </span><span class="nv">TOKEN</span><span class="o">=</span>&lt;TOKEN&gt;
curl <span class="nt">-sfL</span> https://get.k3s.io | <span class="nv">K3S_URL</span><span class="o">=</span>https://192.168.0.100:6443 <span class="nv">K3S_TOKEN</span><span class="o">=</span><span class="nv">$TOKEN</span> <span class="se">\</span>
  <span class="nv">INSTALL_KUBE_EXEC</span><span class="o">=</span><span class="s2">"--node-label memory=medium --node-label=gpu=nvidia"</span> sh -
</code></pre></div></div>

<h3 id="container-configuration">Container Configuration</h3>

<p>Consult the K3s <a href="https://rancher.com/docs/k3s/latest/en/advanced/#configuring-containerd">Advanced Options and Configuration Guide</a>; for this type of node we are specifically concerned with setting the container runtime to <code class="language-plaintext highlighter-rouge">nvidia-container-runtimenvidia-container-runtime</code>. First stop the <code class="language-plaintext highlighter-rouge">k3s-agent</code> service with <code class="language-plaintext highlighter-rouge">sudo systemctl stop k3s-agent</code>. Then create the file <a href="scripts/containerd/containerd/config.toml.tmpl">/var/lib/rancher/k3s/agent/etc/containerd/config.toml.tmpl</a>, and add the following content:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">[</span>plugins.opt]
  path <span class="o">=</span> <span class="s2">""</span>

<span class="o">[</span>plugins.cri]
  stream_server_address <span class="o">=</span> <span class="s2">"127.0.0.1"</span>
  stream_server_port <span class="o">=</span> <span class="s2">"10010"</span>
  disable_cgroup <span class="o">=</span> <span class="nb">true
  </span>disable_apparmor <span class="o">=</span> <span class="nb">true
  </span>restrict_oom_score_adj <span class="o">=</span> <span class="nb">true

  </span>sandbox_image <span class="o">=</span> <span class="s2">""</span>

<span class="o">[</span>plugins.cri.cni]
  bin_dir <span class="o">=</span> <span class="s2">""</span>
  conf_dir <span class="o">=</span> <span class="s2">""</span>


<span class="o">[</span>plugins.cri.containerd.runtimes.runc]
  <span class="c"># ---- changed from 'io.containerd.runc.v2' for GPU support</span>
  runtime_type <span class="o">=</span> <span class="s2">"io.containerd.runtime.v1.linux"</span>

<span class="c"># ---- added for GPU support</span>
<span class="o">[</span>plugins.linux]
  runtime <span class="o">=</span> <span class="s2">"nvidia-container-runtime"</span>


<span class="o">[</span>plugins.cri.registry.mirrors]

<span class="o">[</span>plugins.cri.registry.mirrors.<span class="s2">""</span><span class="o">]</span>
  endpoint <span class="o">=</span> <span class="o">[</span>, <span class="o">]</span>


<span class="o">[</span>plugins.cri.registry.configs.<span class="s2">""</span>.auth]
  username <span class="o">=</span> <span class="s2">""</span>
  password <span class="o">=</span> <span class="s2">""</span>
  auth <span class="o">=</span> <span class="s2">""</span>
  identitytoken <span class="o">=</span> <span class="s2">""</span>


<span class="o">[</span>plugins.cri.registry.configs.<span class="s2">""</span>.tls]
  ca_file <span class="o">=</span> <span class="s2">""</span>
  cert_file <span class="o">=</span> <span class="s2">""</span>
  key_file <span class="o">=</span> <span class="s2">""</span>


</code></pre></div></div>

<p>Now restart K3s with <code class="language-plaintext highlighter-rouge">sudo systemctl restart k3s-agent</code>.</p>

<h3 id="test-gpu-support">Test GPU Support</h3>

<p>Nvidia created a Docker image that will test to make sure all devices are configured properly. Change into your home directoy, and copy over the demos: <code class="language-plaintext highlighter-rouge">cp -R /usr/local/cuda/samples .</code>. Next, create a <a href="tests/Dockerfile.deviceQuery">Dockerfile.deviceQuery</a> to perform the <code class="language-plaintext highlighter-rouge">deviceQuery</code> test:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>FROM nvcr.io/nvidia/l4t-base:r32.5.0
RUN apt-get update <span class="o">&amp;&amp;</span> apt-get <span class="nb">install</span> <span class="nt">-y</span> <span class="nt">--no-install-recommends</span> make g++
COPY ./samples /tmp/samples
WORKDIR /tmp/samples/1_Utilities/deviceQuery
RUN make clean <span class="o">&amp;&amp;</span> make
CMD <span class="o">[</span><span class="s2">"./deviceQuery"</span><span class="o">]</span>
</code></pre></div></div>

<ol>
  <li>Build: <code class="language-plaintext highlighter-rouge">docker build -t xift/jetson_devicequery:r32.5.0 . -f Dockerfile.deviceQuery</code></li>
  <li>Run: <code class="language-plaintext highlighter-rouge">docker run --rm --runtime nvidia xift/jetson_devicequery:r32.5.0</code></li>
  <li>If everything is configured correctly you should see something like:</li>
</ol>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>deviceQuery, CUDA Driver <span class="o">=</span> CUDART, CUDA Driver Version <span class="o">=</span> 10.2, CUDA Runtime Version <span class="o">=</span> 10.2, NumDevs <span class="o">=</span> 1
Result <span class="o">=</span> PASS
</code></pre></div></div>

<p>By default, K3s will use containerd to run containers so lets ensure that works properly (CUDA support). For this, we will create a simple <a href="tests/containerd/test_containerd_gpu.sh">bash script</a> that uses <code class="language-plaintext highlighter-rouge">ctr</code> instead of <code class="language-plaintext highlighter-rouge">docker</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c">#!/bin/bash</span>

<span class="nv">IMAGE</span><span class="o">=</span>xift/jetson_devicequery:r32.5.0
<span class="nb">export </span><span class="nv">KUBECONFIG</span><span class="o">=</span>/etc/rancher/k3s/k3s.yaml
ctr i pull docker.io/<span class="k">${</span><span class="nv">IMAGE</span><span class="k">}</span>
ctr run <span class="nt">--rm</span> <span class="nt">--gpus</span> 0 <span class="nt">--tty</span> docker.io/<span class="k">${</span><span class="nv">IMAGE</span><span class="k">}</span> deviceQuery
</code></pre></div></div>

<p>You should get the same result as above. The final, and real, test is to deploy a pod to the cluster (selecting only those nodes with the <code class="language-plaintext highlighter-rouge">gpu: nvidia</code> label). Create the following file, <a href="tests/pod_device_query.yaml">pod_device_query.yaml</a>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>apiVersion: v1
kind: Pod
metadata:
  name: devicequery
spec:
  containers:
  - name: nvidia
    image: xift/jetson_devicequery:r32.5.0
    <span class="nb">command</span>: <span class="o">[</span> <span class="s2">"./deviceQuery"</span> <span class="o">]</span>
  nodeSelector:
    gpu: nvidia
</code></pre></div></div>

<p>Create this pod with <code class="language-plaintext highlighter-rouge">kubectl apply -f pod_deviceQuery.yaml</code>, once the image is pulled and the container is created, it will run the <code class="language-plaintext highlighter-rouge">deviceQuery</code> command and then exit, so it may look as if the pod failed. Simply take a look at the logs and look for the above <code class="language-plaintext highlighter-rouge">PASS</code>, with <code class="language-plaintext highlighter-rouge">kubectl logs devicequery</code>. If all checks out we are now ready to deploy GPU workloads to our K3s cluster!</p>

<p><em>Note</em> you may also want to taint this node so that non-GPU workloads will not be scheduled.</p>

<h3 id="pytorch">Pytorch</h3>

<p>Luckily for us, Nvidia has build some Docker images specifically for ARM architecture - L4T. NVIDIA L4T is a Linux based software distribution for the NVIDIA Jetson embedded computing platform. On the node pull and run the image:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker pull nvcr.io/nvidia/l4t-pytorch:r32.6.1-pth1.9-py3
docker run <span class="nt">-it</span> <span class="nt">--rm</span> <span class="nt">--runtime</span> nvidia nvcr.io/nvidia/l4t-pytorch:r32.6.1-pth1.9-py3 python3 <span class="nt">-c</span> <span class="s2">"import torch; print(torch.cuda.is_available());"</span>
</code></pre></div></div>

<p>If all works correctly you should see <code class="language-plaintext highlighter-rouge">True</code> printed out. This just shows how to run a Docker image, it is trivial to create a Pod definition that will use this image (as shown above).</p>

<h3 id="gan">GAN</h3>

<p>That is not an actual application though, stand by and I will deploy a little GAN application using PyTorch and Flask :)</p>]]></content><author><name>Mitch Murphy</name></author><category term="time-series" /><category term="sarima" /><category term="forecasting" /><category term="stock" /><summary type="html"><![CDATA[Howto guide for setting up and configuring a K3s cluster to perform AI/ML on the edge]]></summary></entry></feed>